Meta details Prometheus, an Ohio supercluster heading toward 1 million GPUs
Meta published engineering details of its Prometheus supercluster in New Albany, Ohio, saying it already runs hundreds of thousands of Nvidia GPUs across several buildings and is planned to grow to roughly 1 million operating in lockstep. The first gigawatt-scale phase is finished and was used to train Meta's Muse family of models, including Muse Wonder, on Nvidia GB200 NVL72 and GB300 NVL72 racks, with Vera Rubin NVL72 planned for a third platform. Meta says a year of engineering cut training interruptions by 99%, from nearly 1,000 per 8,000 GPUs per day in mid-2025 to about 11, and that each 72-GPU rack trains on a 64-GPU slice with eight GPUs kept as spares.
Meta's post gives a rare detailed account of the reliability, power-management and redundancy engineering behind a gigawatt-scale AI training cluster, and Meta says its next supercluster, Hyperion in Louisiana, is being designed with these lessons.
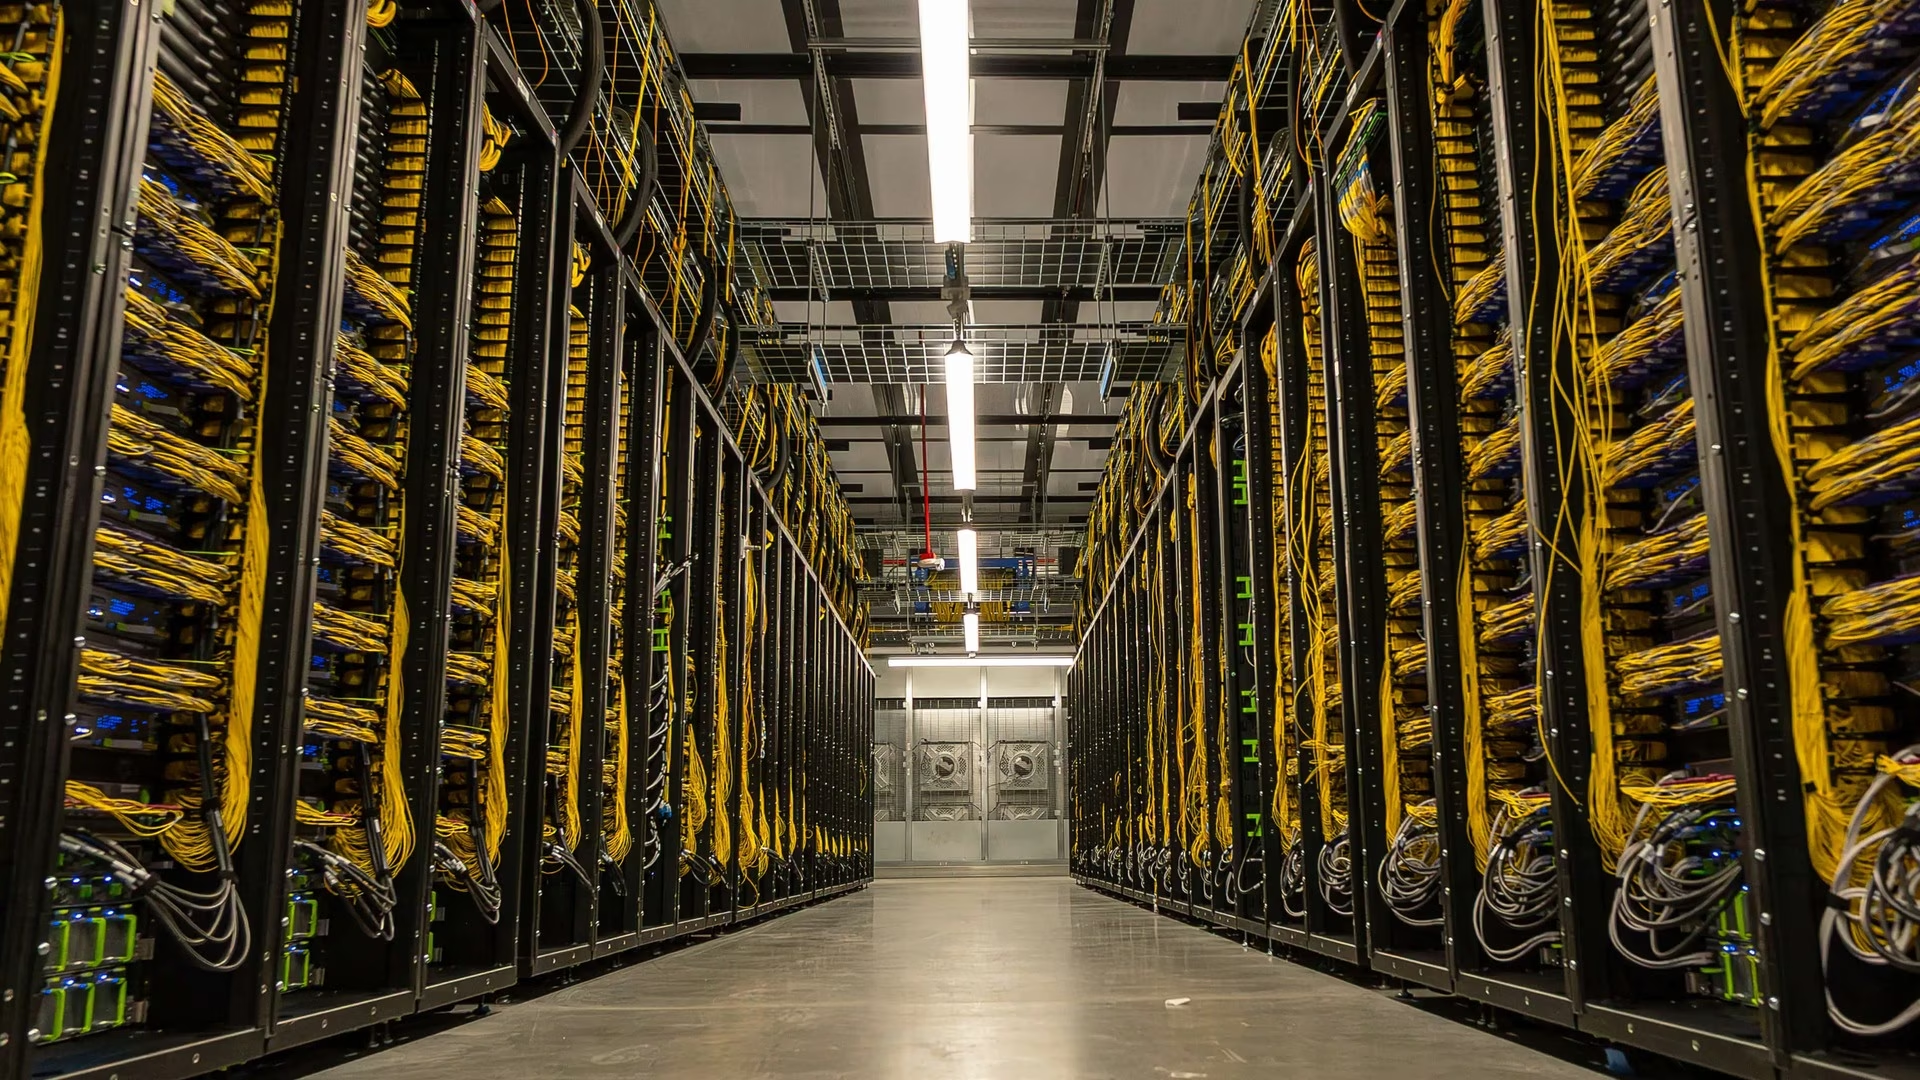

Meta’s Prometheus supercluster in New Albany, Ohio, already runs hundreds of thousands of Nvidia GPUs across several buildings, and Meta plans to grow it to about 1 million. The company set out the details in an engineering blog post on Monday.
The first phase of the gigawatt-scale cluster is finished. Meta used it to train its Muse family of models, including the Muse Wonder models. Two years ago, the site was a conventional data centre running web traffic.
#Meta#Nvidia#Prometheus#Muse Wonder#Muse#GB200 NVL72#GB300 NVL72#Vera Rubin NVL72#Dynamo Dimmer#Hyperion