Lev reuses weights to deepen decisions through repeated computation
Researchers from Lehigh University and other institutions proposed Lev, a decision model that uses repeated computation rather than token generation to increase reasoning depth. According to the researchers, the same weights support multiple depths, with a lightweight stopping mechanism determining how many rounds to run. The model reads option probabilities after each round, and its rounds are jointly trained. On the 231-question public JevBench, project records for the same Lev-2.6B checkpoint show accuracy rising from 63.2% after one round to 76.2% after four rounds, a 13.0 percentage-point increase without changing the checkpoint weights. The report notes that these figures are replayed project-homepage records rather than live inference results.
Lev offers an open-source approach to controlling decision depth with one set of weights, while allowing additional computation for questions that require it. The report describes the architecture as a System 1.5-style design that preserves direct decision-making while permitting deeper computation on harder problems. It also says serving with k rounds requires computing only those rounds, although the reported benchmark figures are project records rather than live inference results.
11月2日消息,近日,来自美国宾州里海大学 Lehigh University 等机构的研究者提出 Lev,一个用循环而不是 token 来加深思考的决策模型。Lev 在每一圈之后都读出一次选项概率,各圈联合训练,所以同一份权重可以在任意深度作答;一个轻量的停止器再按题目决定算几圈。
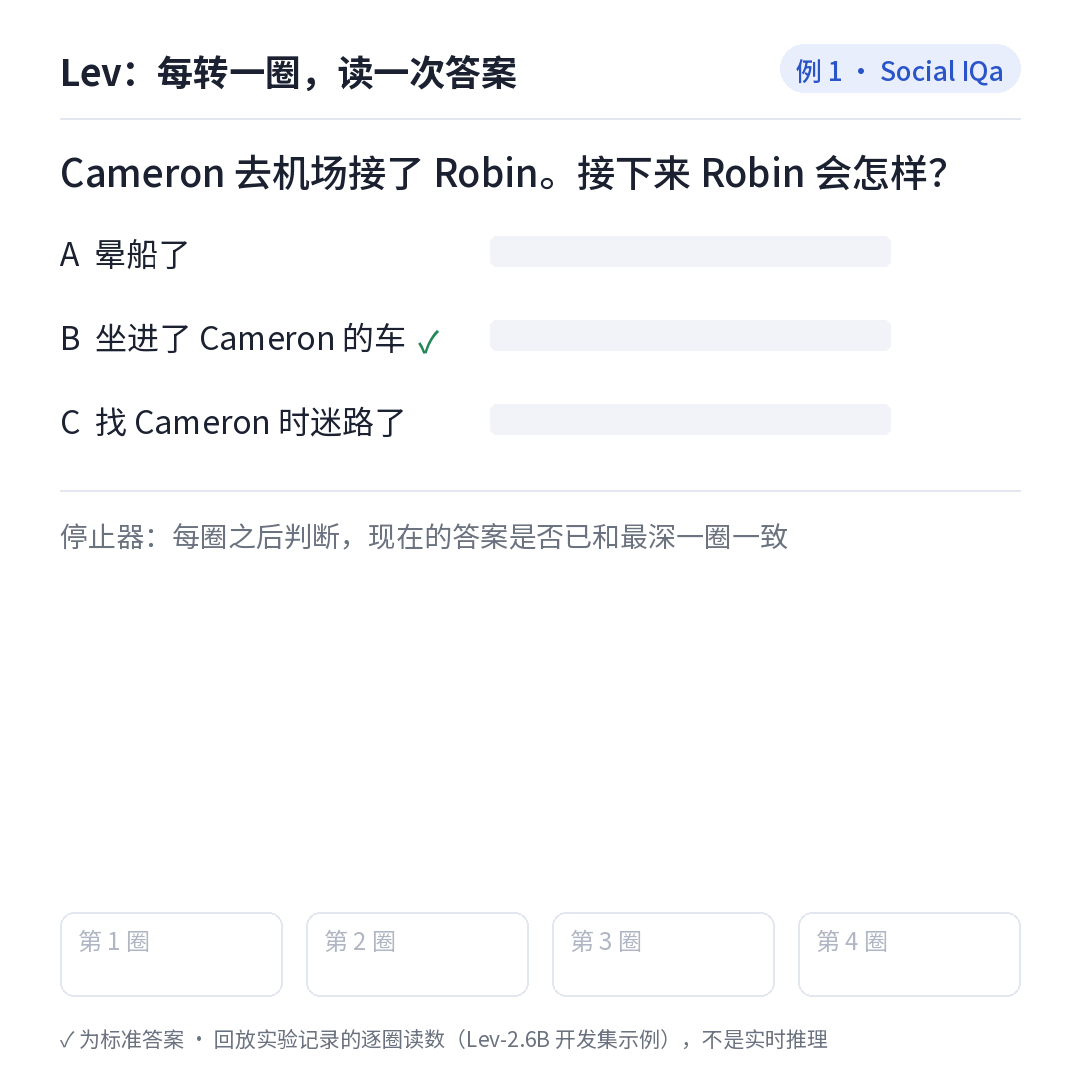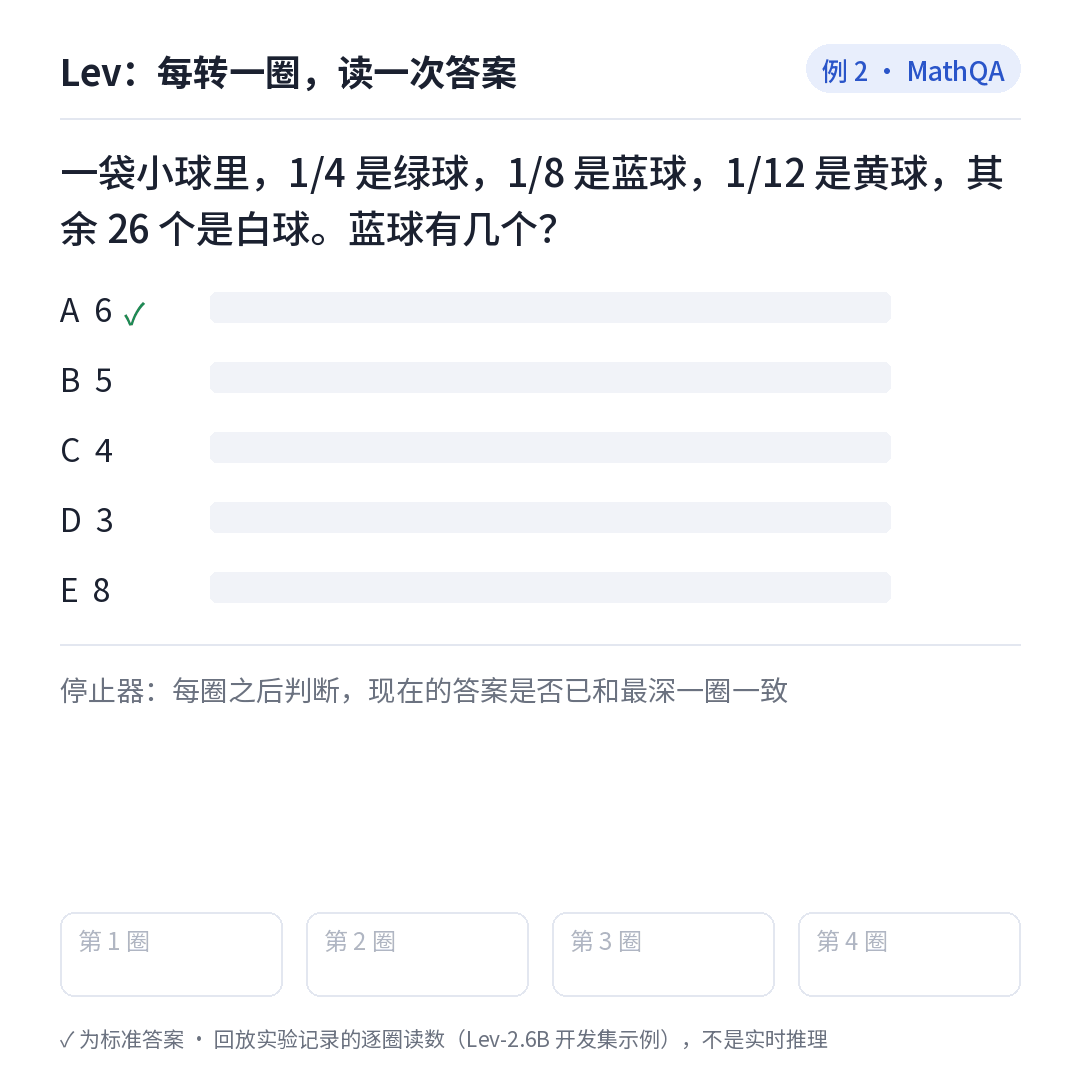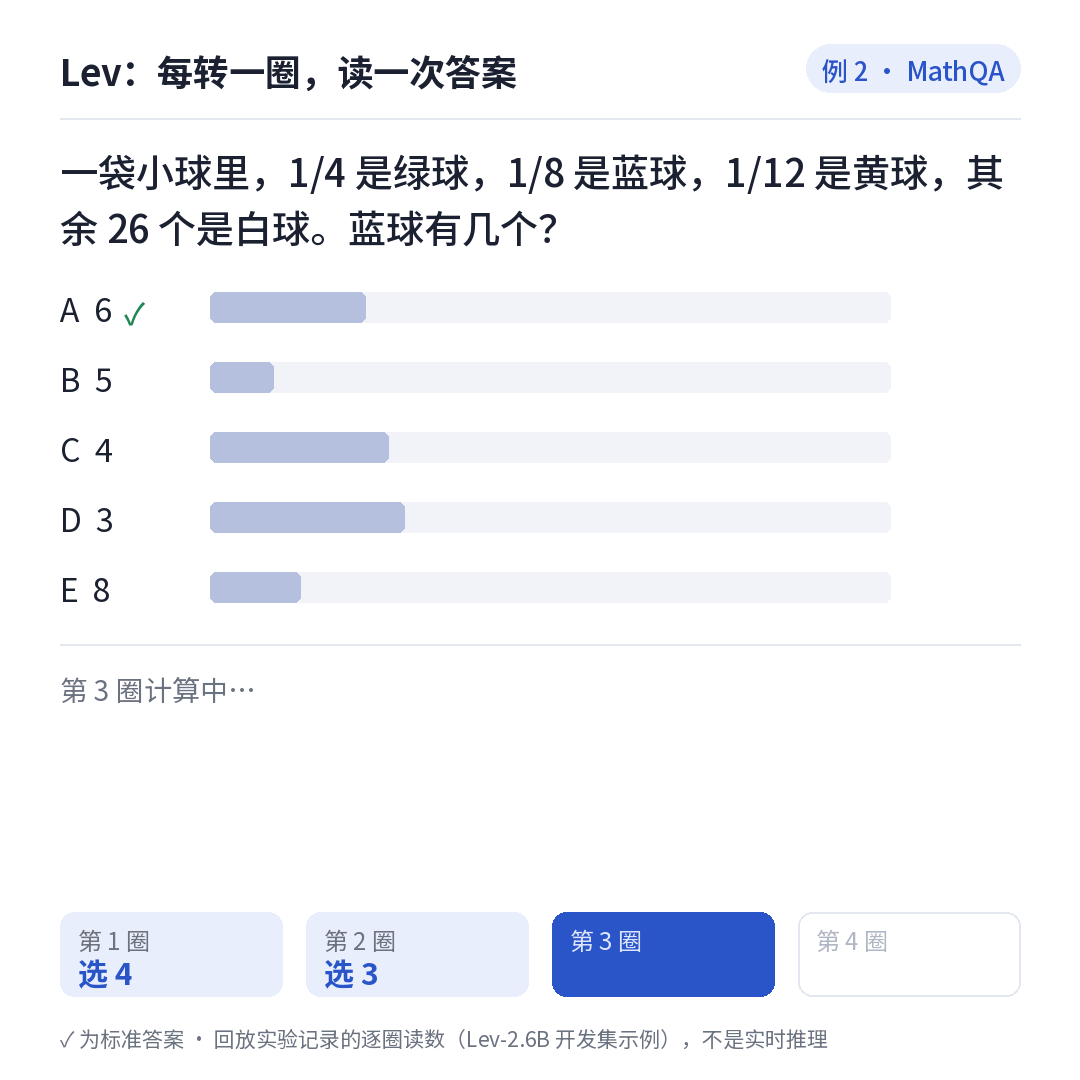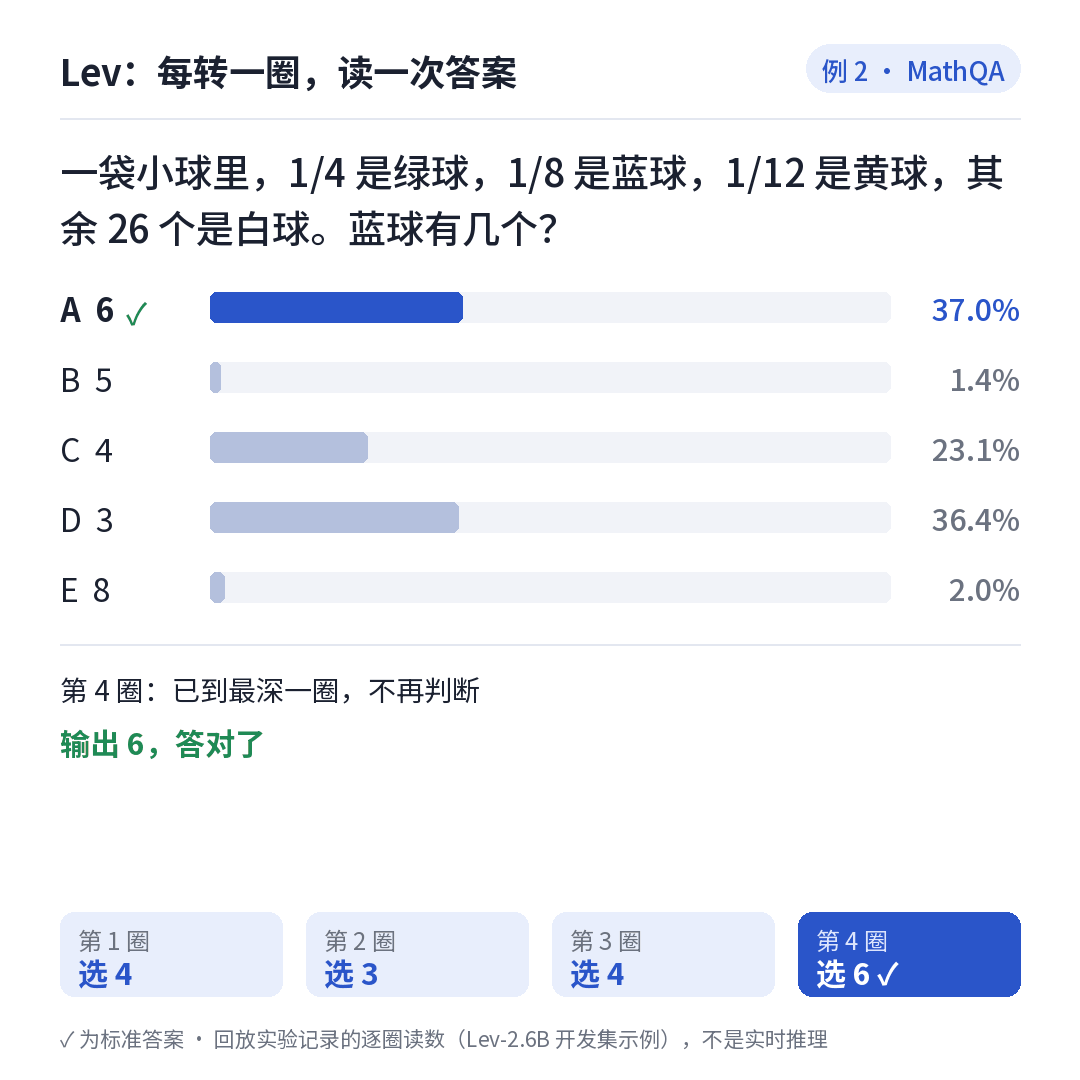
作者把这种计算方式称为 System 1.5 :保留 System 1 直接给出决定的接口,又能像 System 2 一样在难题上多花计算。
Lev 逐圈作答(按项目主页记录的逐圈读数重绘,回放实验数据,不是实时推理):例 1 第 1 圈就选中正确答案 B,停止器判定可以停下;例 2 第 1 圈选 4,到第 4 圈改选正确答案 6。
从任务形态看,Lev 可以视为 OpenAI Decisions 式文本决策的一个独立开源实现,并多了一个「深度旋钮」。这里的「式」只指任务形态:给定输入和候选项,输出每个选项的概率。Lev 基于公开的 Ouro、Nanbeige 底座和 Kev 实现,不复刻 OpenAI 的模型权重、内部架构或 API,也没有与其产品做性能对测。
#Lev#Lehigh University#Ouro#Nanbeige4.2#Kev#JevBench#OpenAI Decisions