韩国KV Cache会议聚焦大模型推理优化
PyTorchKR与XCENA于2026年9月30日联合举办KVCache Meetup Korea,XCENA、SK hynix、FuriosaAI和LMCache分享了技术实践。议题涵盖CXL内存扩展、GPU与HBM瓶颈、RNGD请求调度、LMCache MP Mode,以及XCENA开源的Maru KV Cache存储引擎。72份问卷反馈肯定了议程和交流机会,同时指出麦克风质量、屏幕可视性、场地空间及英文演讲缺少翻译等问题。
这场活动让大模型服务、内存与硬件从业者共同比较KV Cache存储、复用、调度和数据搬运的实际方案。
On the evening of Sep 30, 2026, PyTorchKR and XCENA co-hosted KVCache Meetup Korea. PyTorchKR is a major AI/ML community in Korea, and XCENA is a startup that focuses on CXL (Compute Express Link). Tensormesh, the company behind LMCache, also sponsored the event. Speakers from XCENA, SK hynix, FuriosaAI, and LMCache shared their work on large language model (LLM) inference and KV Cache optimization. LLM inference runs a language model to generate output. KV Cache stores attention data for reuse during inference.
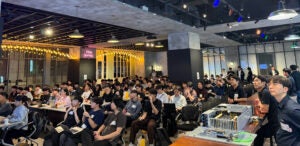
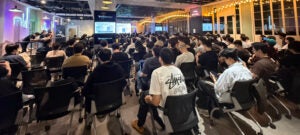
Attendees at KVCache Meetup Korea 2026.
Talks covered CXL memory expansion, GPU and high-bandwidth memory (HBM) bottlenecks, request scheduling on RNGD, and LMCache MP Mode. The sessions showed how hardware and serving software handle KV Cache in different ways. Serving software processes requests that run a model.
#KVCache Meetup Korea 2026#PyTorchKR#XCENA#Tensormesh#LMCache#SK hynix#FuriosaAI#Maru#Furiosa-LLM#RNGD