KVCache Meetup Korea 2026 spotlights LLM inference optimization
PyTorchKR and XCENA co-hosted KVCache Meetup Korea on September 30, 2026, with presentations from XCENA, SK hynix, FuriosaAI, and LMCache. The talks covered CXL memory expansion, GPU and HBM bottlenecks, request scheduling on RNGD, LMCache MP Mode, and XCENA’s open-source Maru KV Cache storage engine. Feedback from 72 survey respondents praised the program and networking, while also identifying issues with microphone quality, screen visibility, limited space, and a lack of interpretation for English talks.
The event brought together LLM serving, memory, and hardware practitioners to compare practical approaches to KV Cache storage, reuse, scheduling, and data movement.
On the evening of Sep 30, 2026, PyTorchKR and XCENA co-hosted KVCache Meetup Korea. PyTorchKR is a major AI/ML community in Korea, and XCENA is a startup that focuses on CXL (Compute Express Link). Tensormesh, the company behind LMCache, also sponsored the event. Speakers from XCENA, SK hynix, FuriosaAI, and LMCache shared their work on large language model (LLM) inference and KV Cache optimization. LLM inference runs a language model to generate output. KV Cache stores attention data for reuse during inference.
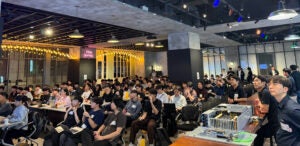
Attendees at KVCache Meetup Korea 2026.
Talks covered CXL memory expansion, GPU and high-bandwidth memory (HBM) bottlenecks, request scheduling on RNGD, and LMCache MP Mode. The sessions showed how hardware and serving software handle KV Cache in different ways. Serving software processes requests that run a model.
#KVCache Meetup Korea 2026#PyTorchKR#XCENA#Tensormesh#LMCache#SK hynix#FuriosaAI#Maru#Furiosa-LLM#RNGD