INT21 says AI agents built a Drama 3 Rust runtime in one hour
INT21 says its SwarmOS orchestrated AI agents that autonomously wrote, tested and optimized a Rust inference runtime for Fish Audio’s Drama 3 in about an hour. Its workflow generates multiple candidate implementations, tests them on hardware including NVIDIA B200 GPUs, retains working versions and discards failed ones. INT21’s benchmark reported time to first audio of 15.11–23.58 milliseconds, compared with 37.79–38.61 milliseconds for SGLang-Omni. Each test used one speech stream, a one-frame first chunk and 20 warm trials per prompt across three prompts; the results are INT21’s own reported figures.
The report describes agent-driven runtime optimization as a practical method for improving AI inference efficiency. INT21 reported lower time to first audio and higher throughput for its Drama 3 runtime than for SGLang-Omni on its selected B200 benchmark, while also attributing the one-hour development claim to INT21.
INT21, a self-improving infrastructure startup that 'uses compute to improve compute,' has just refocused the proverbial spotlight on the software and away from the increasingly scarce NVIDIA GPUs, managing to dramatically speed up Fish Audio's Drama 3 model by engineering customized inference runtimes in the Rust coding language via a swarm of AI agents that constructed a viable inference engine in just around an hour.
INT21's unique methodology: AI swarms, Rust coding language instead of Python, and a looped workflow
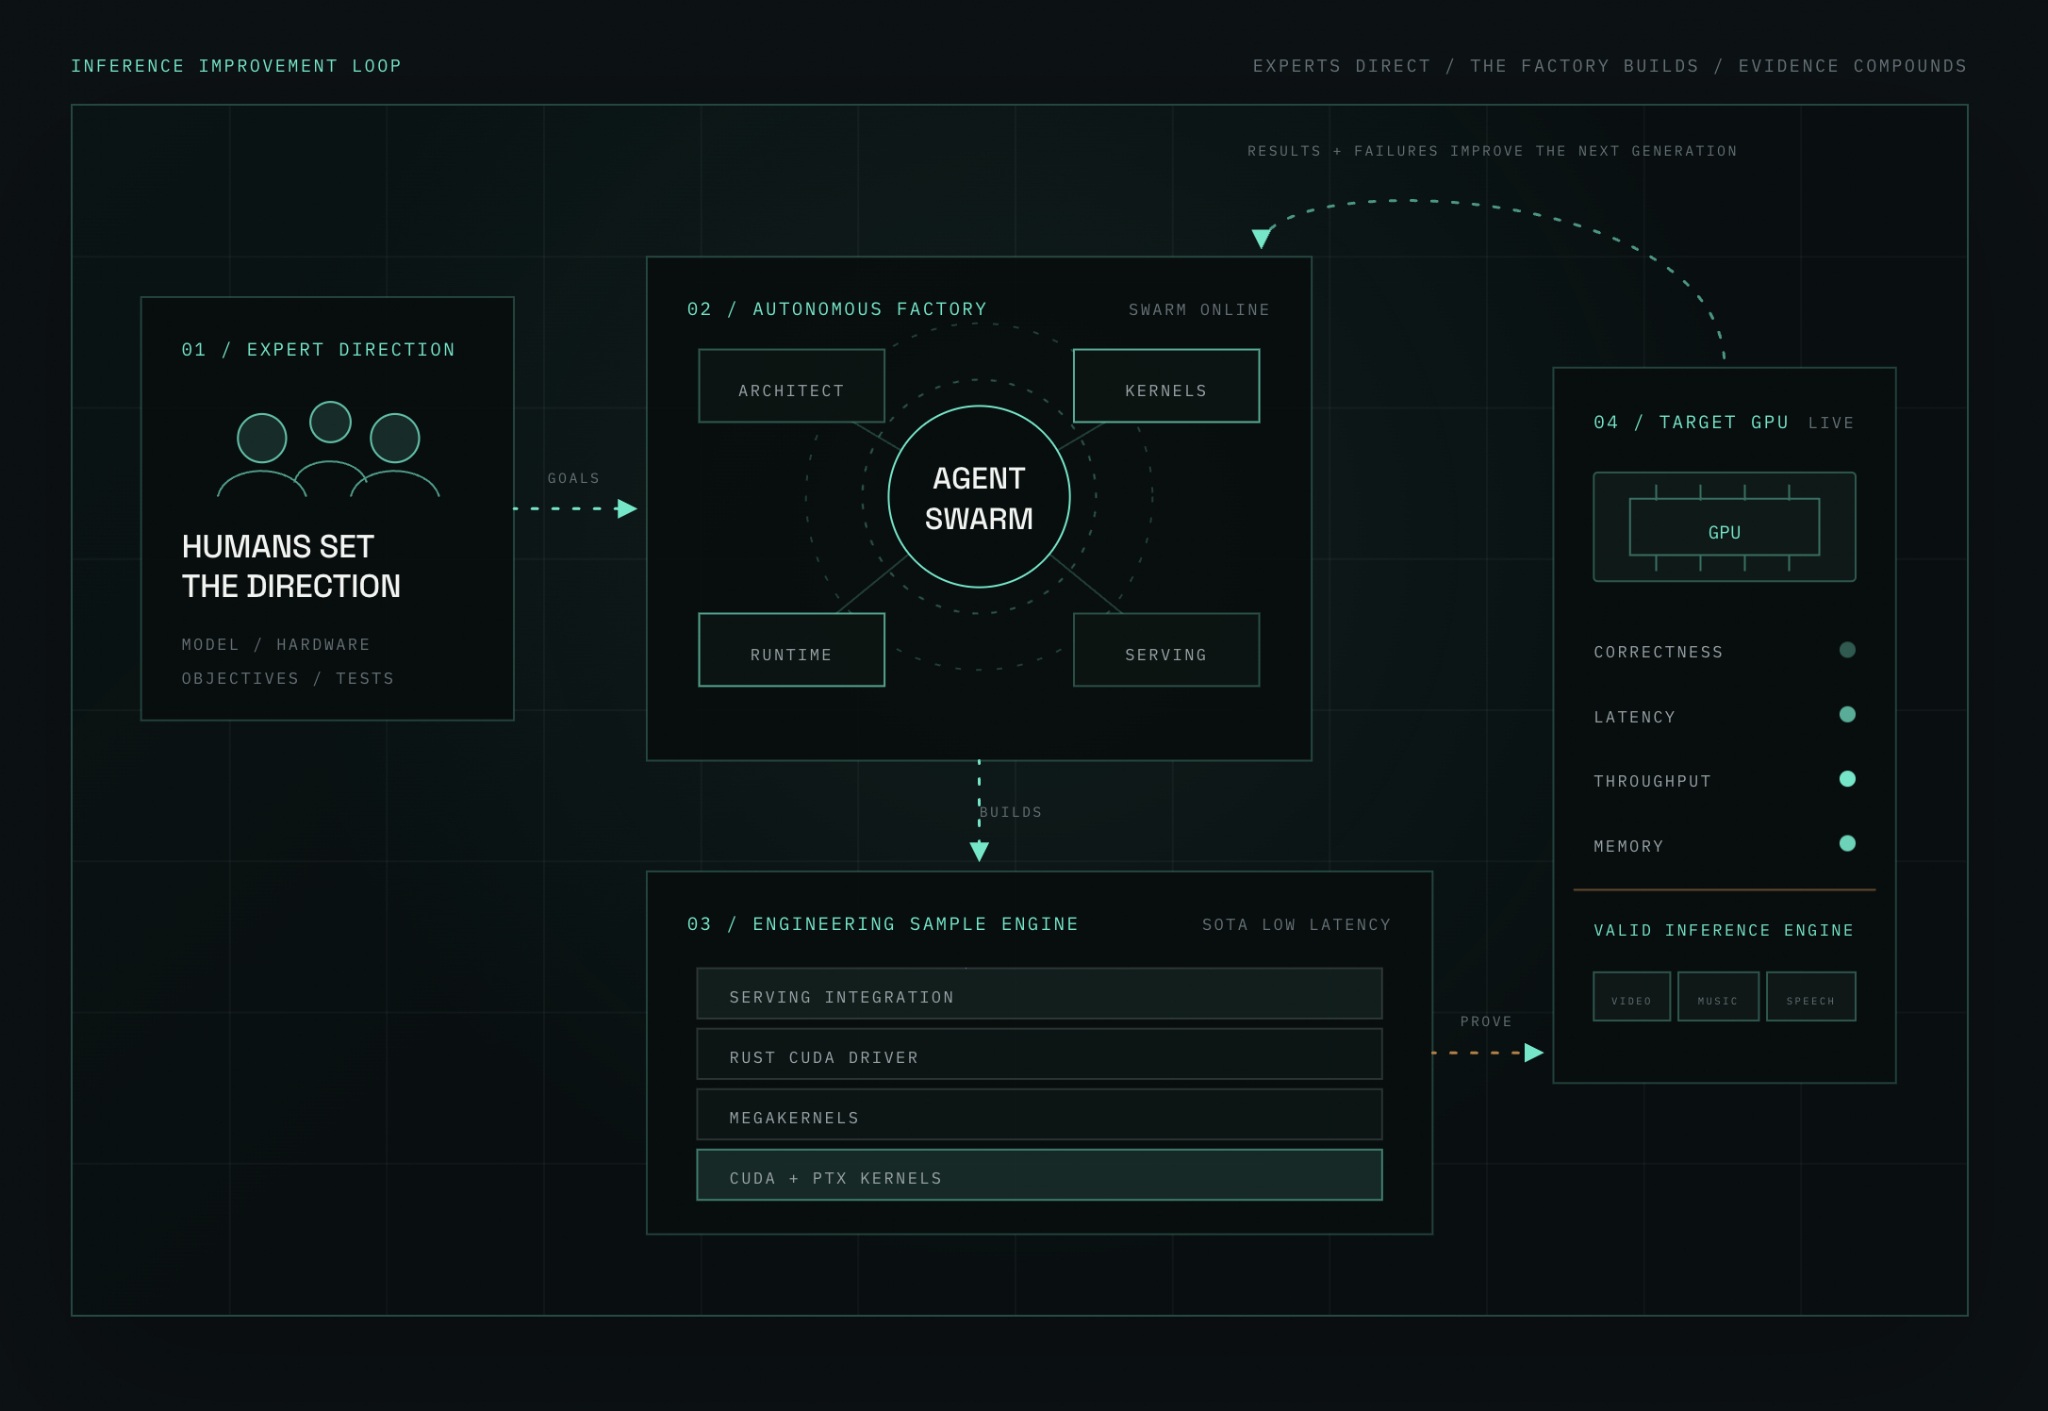
INT21’s core methodology, one that pivots around 'Self-Improving Infrastructure,' flips the traditional software engineering paradigm on its head. Instead of human engineers painstakingly writing the code to run AI models, INT21 uses AI agent swarms to write, test, and optimize that code autonomously.
SwarmOS, a cloud-native platform that orchestrates thousands of AI agents simultaneously, is INT21's secret sauce in this endeavor. These agents operate inside the Inference Engine Factory, a system dedicated strictly to building inference runtimes - the underlying software engine that executes an AI model after it has already been trained, turning user inputs into outputs. These inference engines load model weights into the hardware (GPU, TPU, CPU) and execute the mathematical forward pass to generate tokens, optimizing how fast and efficiently you can run the neural network to produce a faster output.
#INT21#SwarmOS#Inference Engine Factory#Fish Audio#Drama 3#SGLang-Omni#NVIDIA B200#Rust