SGLang 推出低延迟模式与插件内核
SGLang、NVIDIA 与 AMD 团队联合发布 SGLang Low-Latency Mode,通过插件框架把针对低延迟推理优化的专用内核接入 SGLang,其中 NVIDIA 侧为 sgl-nvidia-mega,AMD 侧为 sgl-amd-mono。官方博客称,在基于 DeepSeek-V4.1-Flash 与 DSpark 的 AgentX 轨迹回放中,四块 NVIDIA GB300 在单并发会话下 P90 每用户生成速度从 671.2 提升到 928.4 tokens/s(1.38 倍),四块 AMD MI355X 在四并发会话下从 331.6 提升到 516.0 tokens/s(1.56 倍),均与同硬件上的 SGLang 基线对比。在 8K 输入 / 1K 输出负载、1 至 8 并发请求下,NVIDIA 插件将每用户解码速度提升 12%–38%;团队表示正为 GLM-5.3、K3 和 MiniMax M3 开发相关内核。
该插件框架让内核团队可以发布针对特定模型与硬件的优化,而无需把每一种专用实现都加进 SGLang 核心代码库。
SGLang Low-Latency Mode: Kernels and Runtime
SGLang, NVIDIA and AMD teamsOctober 18, 2026
Low-latency inference offers many opportunities for optimizations tailored to specific models, hardware and workloads. These optimizations often require extensive kernel fusion and duplicate code across implementations, making them difficult to maintain. To support this specialization, we introduce SGLang Low-Latency Mode. It brings specialized kernels into SGLang through a plugin framework and delivers substantial latency reductions on both NVIDIA and AMD GPUs. In AgentX trace replay, these optimizations improve P90 per-user token generation speed by up to 1.38× on NVIDIA GB300 and 1.56× on AMD MI355X compared with the respective SGLang baselines.
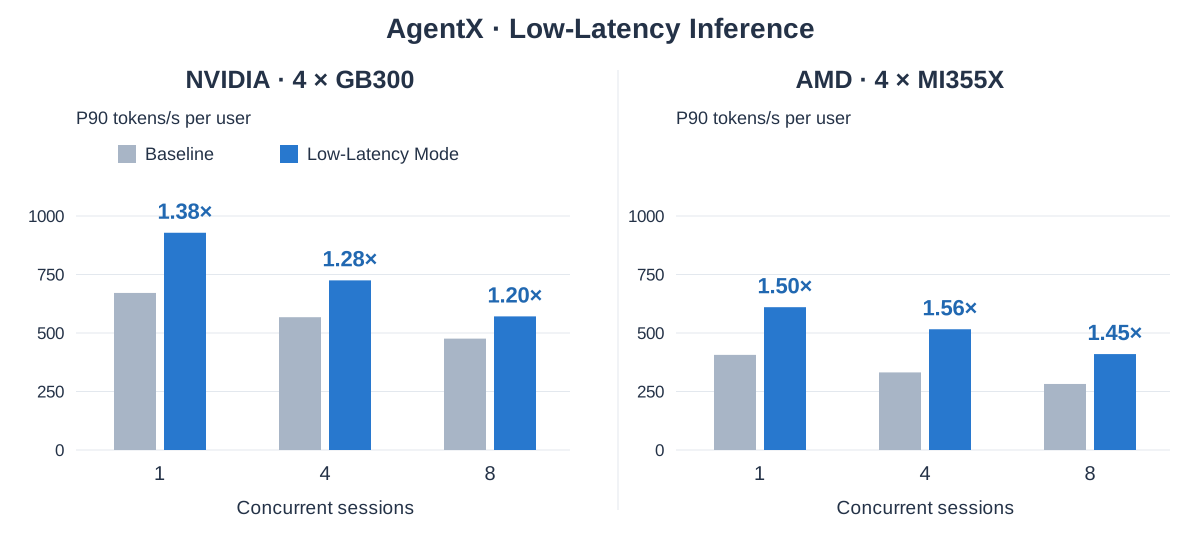
AgentX · DeepSeek-V4.1-Flash with DSpark · NVIDIA GB300 and AMD MI355X.
Table of Contents
#SGLang#NVIDIA#AMD#DeepSeek-V4.1-Flash#DSpark#GLM-5.3#MiniMax M3