微软发布Decision-1决策评分模型,基于Qwen3.5-9B
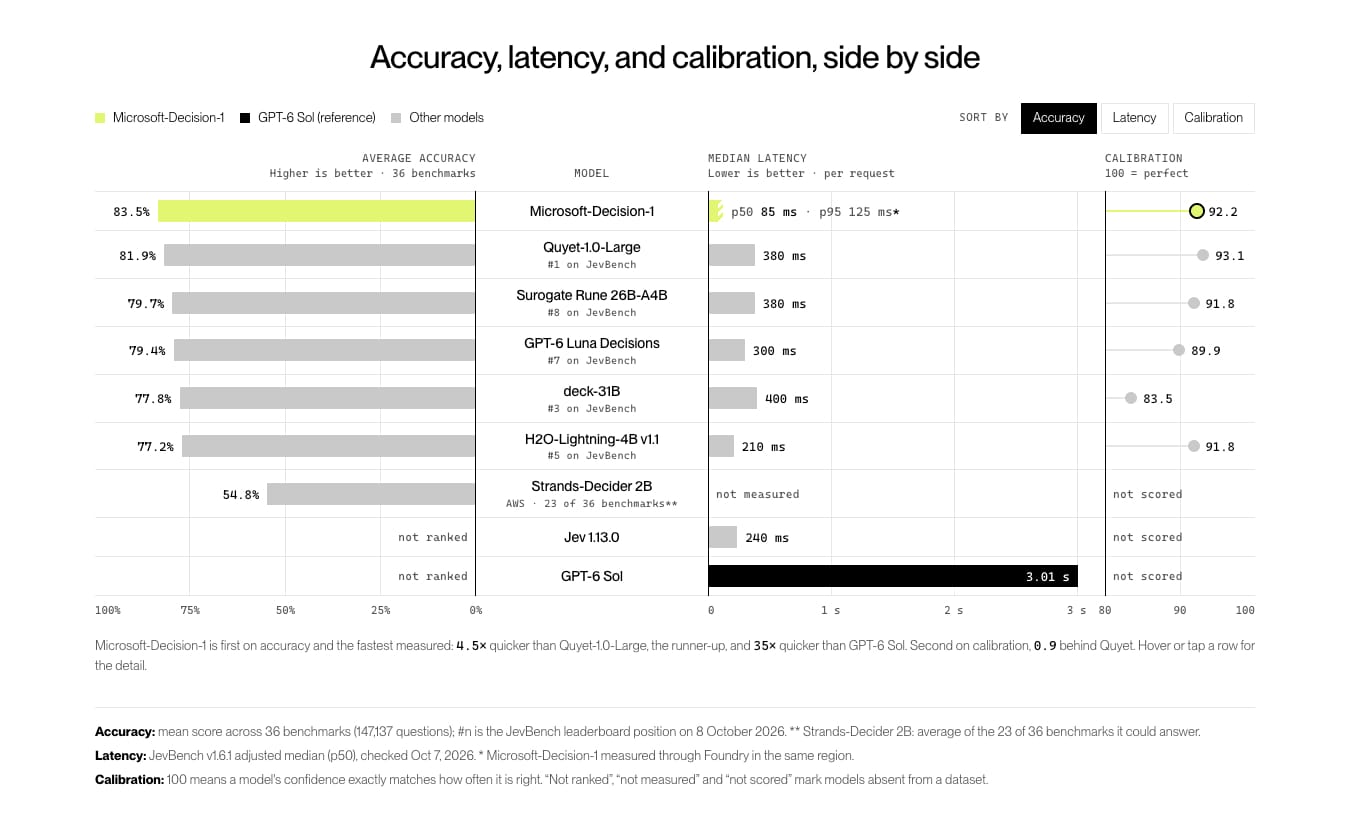
微软发布 Microsoft-Decision-1,一款面向结构化决策评分的专用模型,现已在 Microsoft Foundry 上线,并已登陆 OpenRouter。它基于 Qwen3.5-9B 后训练,针对一组固定选项返回每个选项的校准概率,支持是/否、多选与评分,可用于路由、分类、优先级排序、结果验证与智能体控制等场景。微软称其在覆盖近 15 万道题、36 项基准的评测中准确率最高,P50 延迟为 GPT-6 Sol 的 35 倍(即更快),定价为每百万输入 token 0.042 美元、输出免费;微软还计划未来将系统迁移到其他底座模型,包括 MAI 与 OpenAI 技术。上述性能数据均来自微软自身评测,尚无独立第三方验证。
为什么重要:决策评分模型正成为智能体工作流中的低成本控制层,微软以小型后训练模型切入这一赛道,可能显著压低高频决策任务的延迟与成本。
Microsoft has launched Microsoft-Decision-1, a purpose-built model for fast decision scoring that produces structured choices software can act on immediately. It is available now in Microsoft Foundry and is due on OpenRouter soon. The model targets developers building routing, classification, prioritization, verification, workflow control, agent controls, data labeling, AI judging, search relevance, safety screening, computer use, robotics, and scientific discovery systems.
Rather than generating open-ended text, Microsoft-Decision-1 takes a fixed set of options and returns a calibrated probability for each through a structured API call. It supports yes/no, multiple-choice and rating options, along with rubric-based grading of AI responses and agent actions. Microsoft post-trained Qwen3.5-9B for single-pass scoring and plans to rebase the system on other models, including Microsoft AI and OpenAI technology.
Microsoft says the model achieved the highest accuracy in a 36-benchmark evaluation covering nearly 150,000 questions withheld from training. In the company’s tests, it was 4.5 times faster than runner-up Quyet-1.0-Large and 35 times faster than GPT-6 Sol at P50 latency. Across eight perturbations of equivalent requests, its decision changed 1.3% of the time on average, with no flips when option descriptions were paraphrased or options were reversed or shuffled. Safety testing covered 5,250 requests across 11 benchmarks involving harmful content, jailbreaks and prompt injection.
 Internal trials put the model into practical workflows. Xbox Research used it to label more than 10,000 feedback items and reported quality competitive with GPT-6 Sol while running over 14 times faster and costing 200 times less. The Copilot team found it competitive with GPT-5.6 Luna and 100 times faster. Microsoft also reports gains in incident knowledge retrieval and scientific replanning, where scoring was 46 times more consistent than an LLM-based approach and produced nearly fourfold faster adaptive replanning.
Pricing starts at $0.042 per million input tokens, with output tokens free. Microsoft is positioning the model as a low-cost control layer for agentic systems, where confidence scores can determine whether software acts, defers, retries, escalates or hands work to a model, tool or person.
Sources and related context
- Microsoft-Decision-1 in the Microsoft Foundry catalog: Supports: The official catalog confirms general availability, Qwen3.5-9B post-training, and calibrated probability scoring for fixed answer options.
- Qwen3.5-9B official model card: Related context: The model card describes the open-weight nine-billion-parameter model that Microsoft post-trained for Decision-1.