NVIDIA Model Optimizer Combines Model Optimization Techniques
NVIDIA describes Model Optimizer as an open-source library that combines quantization, pruning, neural architecture search, distillation, speculative decoding and sparsity to accelerate models. It accepts Hugging Face, PyTorch and ONNX models, provides Python APIs for composing optimization techniques and exporting optimized quantized checkpoints, and integrates with Megatron-Bridge, Megatron-LM and Hugging Face Accelerate. The resulting checkpoints can be deployed in SGLang, TensorRT-LLM, TensorRT and vLLM. Its unified Hugging Face export API supports both transformers and diffusers models.
The project gives developers a unified way to combine model optimization techniques and export quantized checkpoints for multiple supported inference frameworks.
A unified library of SOTA model optimization techniques like quantization, distillation, pruning, neural architecture search, speculative decoding, etc. It compresses deep learning models for downstream deployment frameworks like TensorRT-LLM, TensorRT, vLLM, etc. to optimize inference speed.

https://nvidia.github.io/Model-Optimizer/
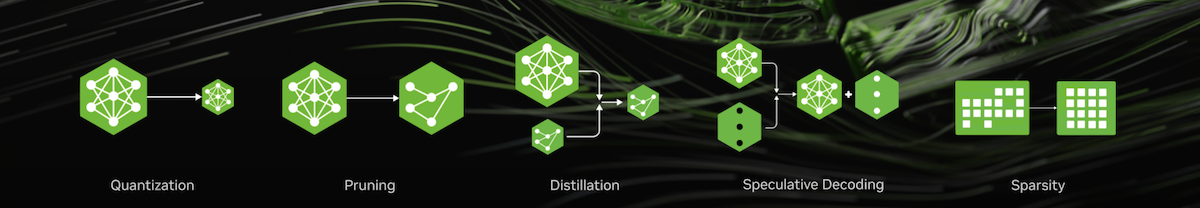
NVIDIA Model Optimizer
#NVIDIA Model Optimizer#TensorRT-LLM#TensorRT#vLLM#SGLang#Hugging Face#PyTorch#ONNX#Megatron-Bridge#Megatron-LM#Hugging Face Accelerate#Diffusers