Meta详解Prometheus:目标约100万颗GPU
Meta 公布其位于俄亥俄州新奥尔巴尼的 Prometheus 超级集群工程细节,称该集群已在多栋建筑中运行数十万颗 Nvidia GPU,并计划扩展至约 100 万颗协同工作。该千兆瓦级集群一期已完工,并用其训练了 Muse 系列模型(包括 Muse Wonder),目前采用 Nvidia GB200 NVL72 与 GB300 NVL72 机架,第三个平台将引入 Vera Rubin NVL72。Meta 称经过一年工程优化,训练中断较 2025 年中期下降 99%,从每 8000 颗 GPU 每日近千次降至约 11 次;每个 72 颗 GPU 的机架实际只用 64 颗训练,其余 8 颗为热备援。
这份披露罕见地详述了千兆瓦级 AI 训练集群在可靠性、电力管理与冗余上的工程设计,Meta 表示下一个位于路易斯安那州的 Hyperion 集群正借鉴这些经验进行设计。
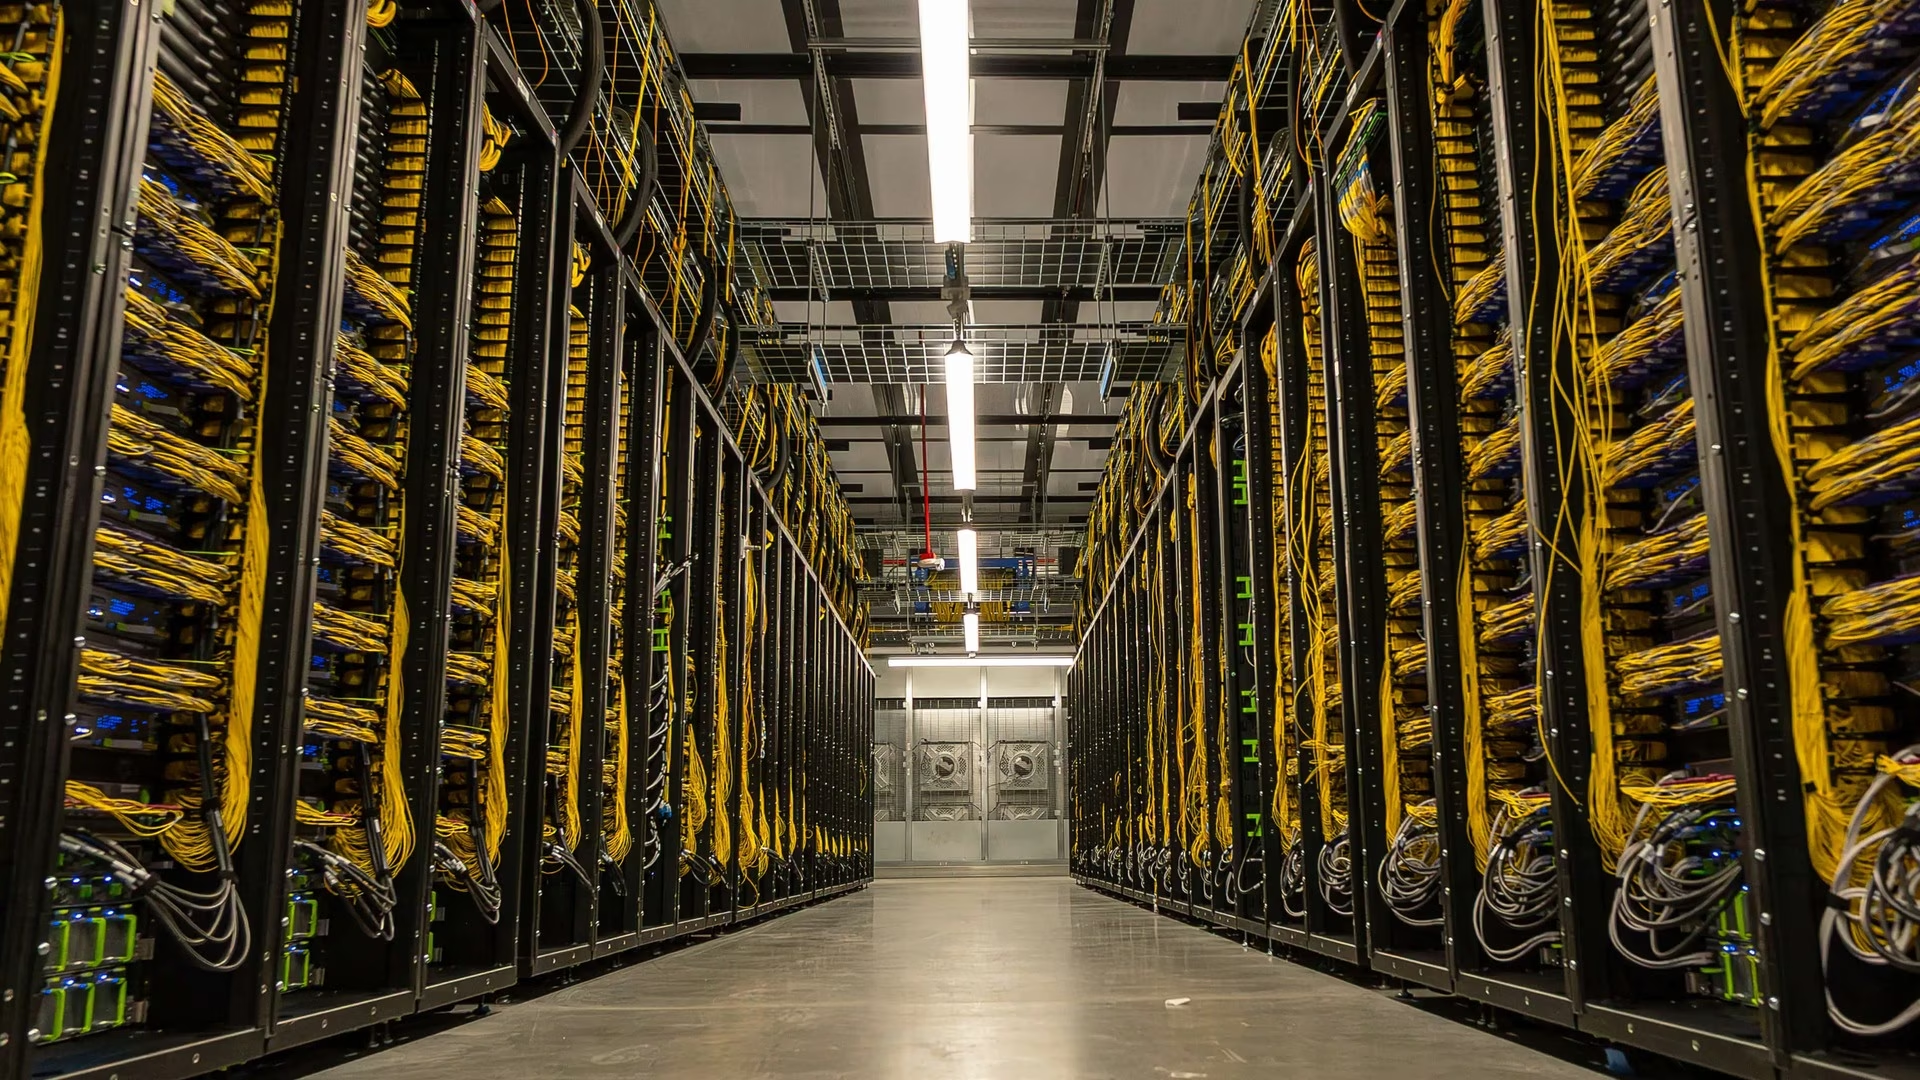

Meta’s Prometheus supercluster in New Albany, Ohio, already runs hundreds of thousands of Nvidia GPUs across several buildings, and Meta plans to grow it to about 1 million. The company set out the details in an engineering blog post on Monday.
The first phase of the gigawatt-scale cluster is finished. Meta used it to train its Muse family of models, including the Muse Wonder models. Two years ago, the site was a conventional data centre running web traffic.
#Meta#Nvidia#Prometheus#Muse Wonder#Muse#GB200 NVL72#GB300 NVL72#Vera Rubin NVL72#Dynamo Dimmer#Hyperion