Karpathy 的 nanochat 提供低成本大模型训练框架
Andrej Karpathy 采用 MIT 许可证的 nanochat 仓库提供了一个精简、可修改的大模型训练实验框架,覆盖分词、预训练、微调、评估和推理等环节。该项目面向单个 GPU 节点运行,用户可通过深度参数选择模型规模,其余超参数由系统自动计算。Karpathy 称,使用 8 张 H100 的节点训练 GPT-2 级别模型约需两小时、成本约 48 美元;在竞价实例上,总成本可接近 15 美元。报道未独立验证这些数据。
nanochat 将完整的大模型训练流程整合进一个易读、可修改且可直接使用的研究代码库。其精简设计和低成本训练主张可能提升小模型实验的可及性,但核心成本、速度和质量数据仍属于开发者陈述,尚未获得独立验证。
The best ChatGPT that $100 can buy.
nanochat
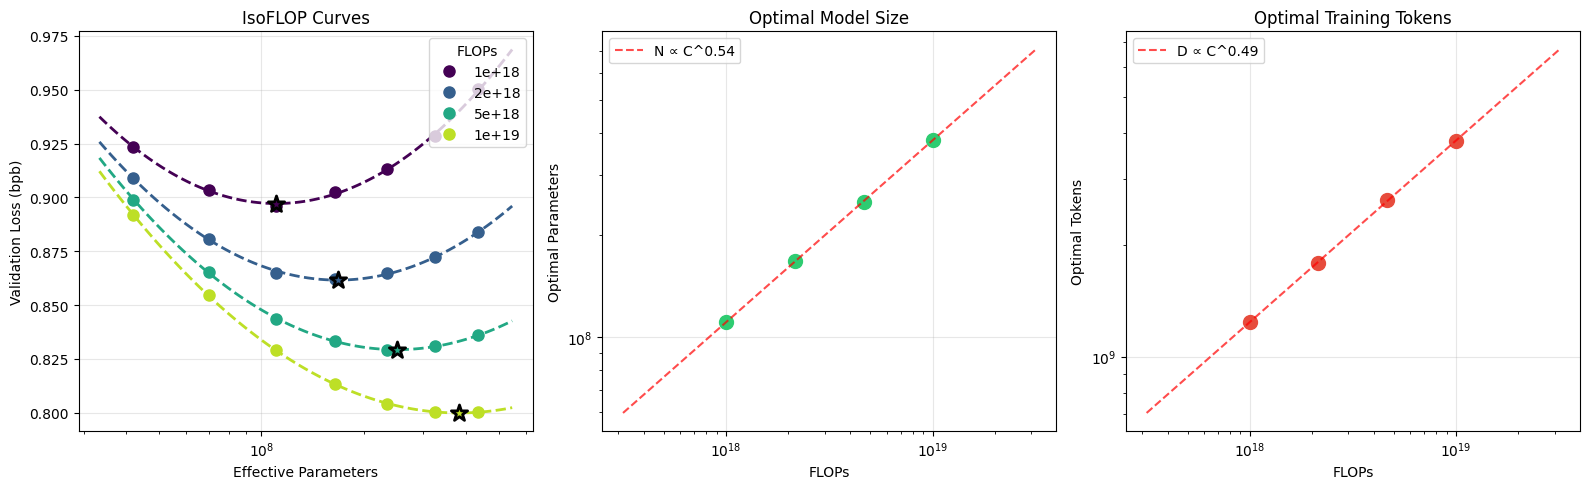
nanochat is the simplest experimental harness for training LLMs. It is designed to run on a single GPU node, the code is minimal/hackable, and it covers all major LLM stages including tokenization, pretraining, finetuning, evaluation, and inference. For example, you can train your own GPT-2 capability LLM (which cost ~$43,000 to train in 2019) for only $48 (~2 hours of 8XH100 GPU node) and then talk to it over a simple CLI. On a spot instance, the total cost can be closer to ~$15. More generally, nanochat is configured out of the box to train an entire miniseries of compute-optimal models by setting one single complexity dial: --depth, the number of layers in the GPT transformer model (GPT-2 capability happens to be approximately depth 26). All other hyperparameters (the width of the transformer, number of heads, learning rate adjustments, training horizons, weight decays, ...) are calculated automatically in an optimal way.
#nanochat#Andrej Karpathy#GPT-2#H100#DCLM CORE#nanoGPT#modded-nanoGPT#Hugging Face#NVIDIA ClimbMix