Buoyant launches open-source Kinference for vLLM
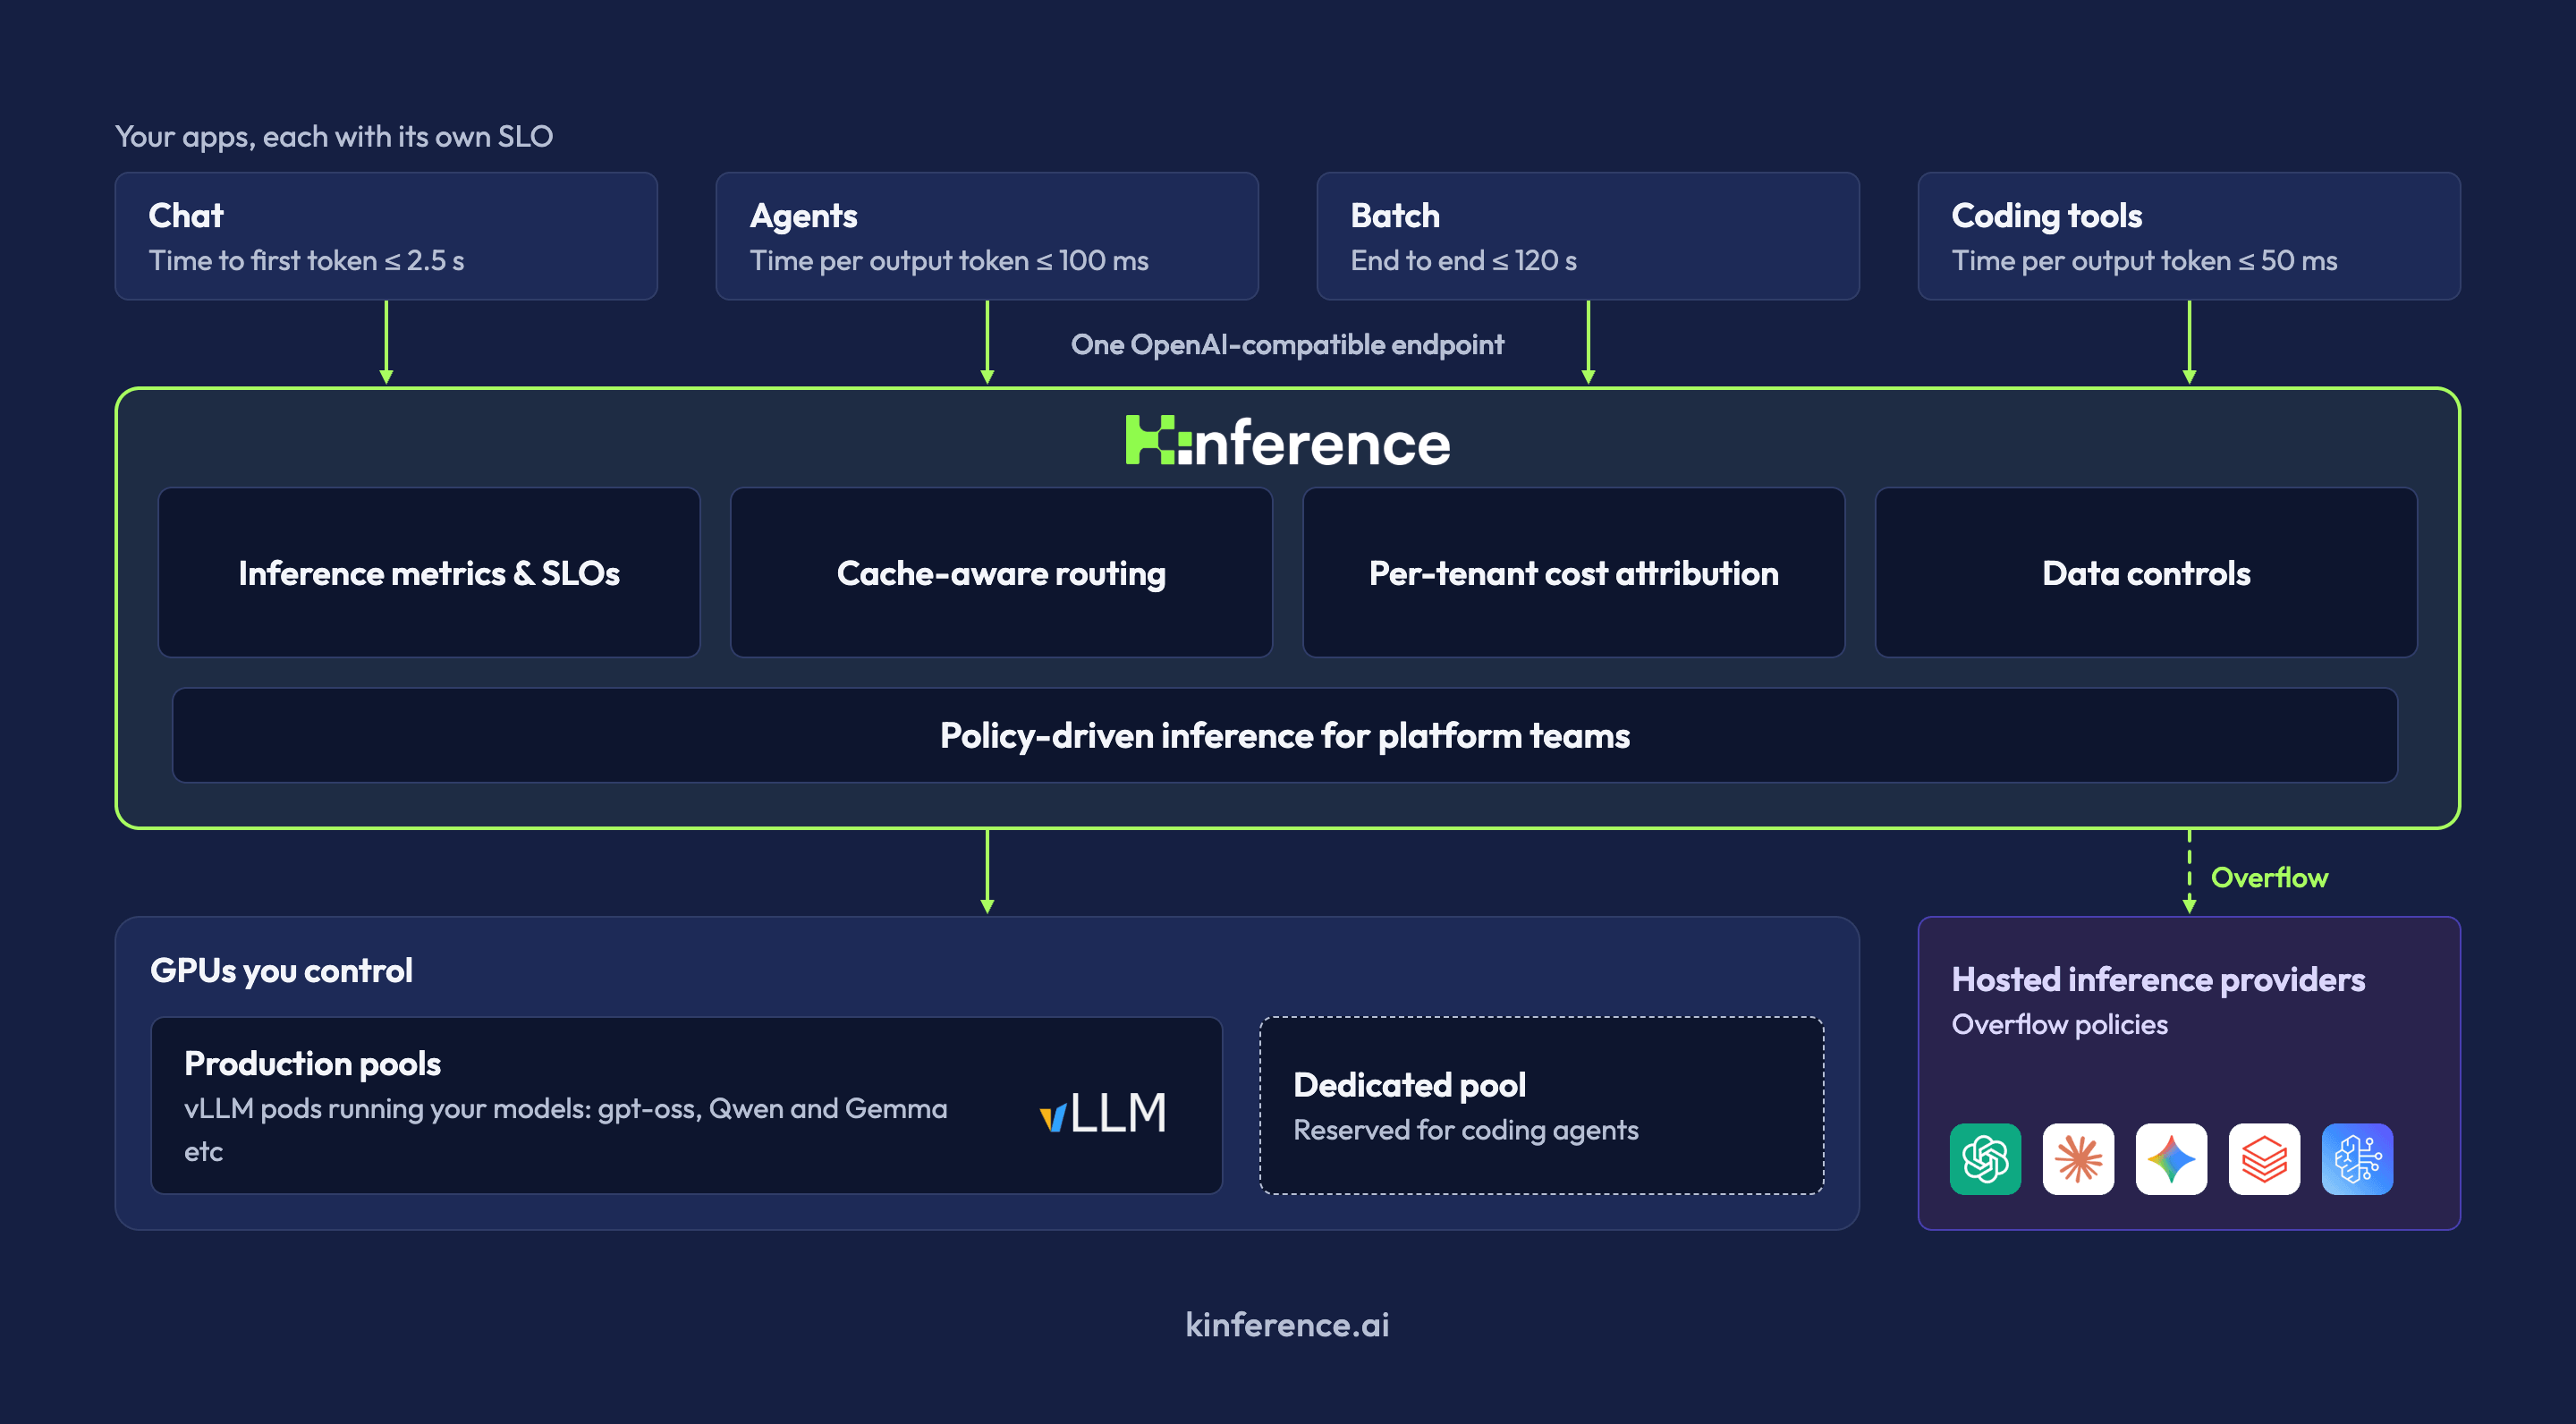
Buoyant announced Kinference, an Apache 2.0-licensed open-source control plane for building inference platforms with vLLM and Kubernetes. It offers token rate limiting, tenant usage and cost tracking, inference-specific load balancing, and policy-based routing through an HTTP endpoint compatible with OpenAI and Anthropic clients. In Buoyant's public benchmarks, Kinference reported lower median time-to-first-token and end-to-end latency than standard Kubernetes load balancing on one workload, along with 7.4 times the goodput on a shared-prefix workload and about 3.5 times on a multiturn workload.
Kinference provides an open-source control layer for operating open-weight models, with policy controls, per-tenant metrics, cost tracking, and load balancing informed by GPU queue sizes, historical performance, and KV-cache contents.
We’re excited to announce Kinference [kay-inference], a new open source project for building scalable inference platforms with vLLM.
We created Kinference at Buoyant after watching our customers struggle to run open weight models in their environments. We designed Kinference to be the control plane layer for the platform you need to build. It uses vLLM to do the underlying inference, and provides the set of features necessary for building an inference platform in practice. This includes token rate limiting, tenant usage and cost tracking, intelligent load balancing, and inference policies.