Inkling 2 Mini 获 vLLM 首日支持
Thinking Machines 发布了 Inkling 2 Mini,这是一款总参数量 26B、激活参数量 3.5B、上下文最长 100 万 token 的多模态 MoE 模型。其中间 12 层会以共享权重运行三次,每次使用独立 KV 缓存,并通过门控消息传递信息。vLLM Blog 称,vLLM 已为 NVIDIA Blackwell、Hopper 和 DGX Spark 提供首日支持,并可服务 TML-d24-varloop-research 检查点。
此次发布同时提供新型循环多模态模型、可立即使用的推理实现、缓存与内核优化细节,以及可变循环研究检查点。
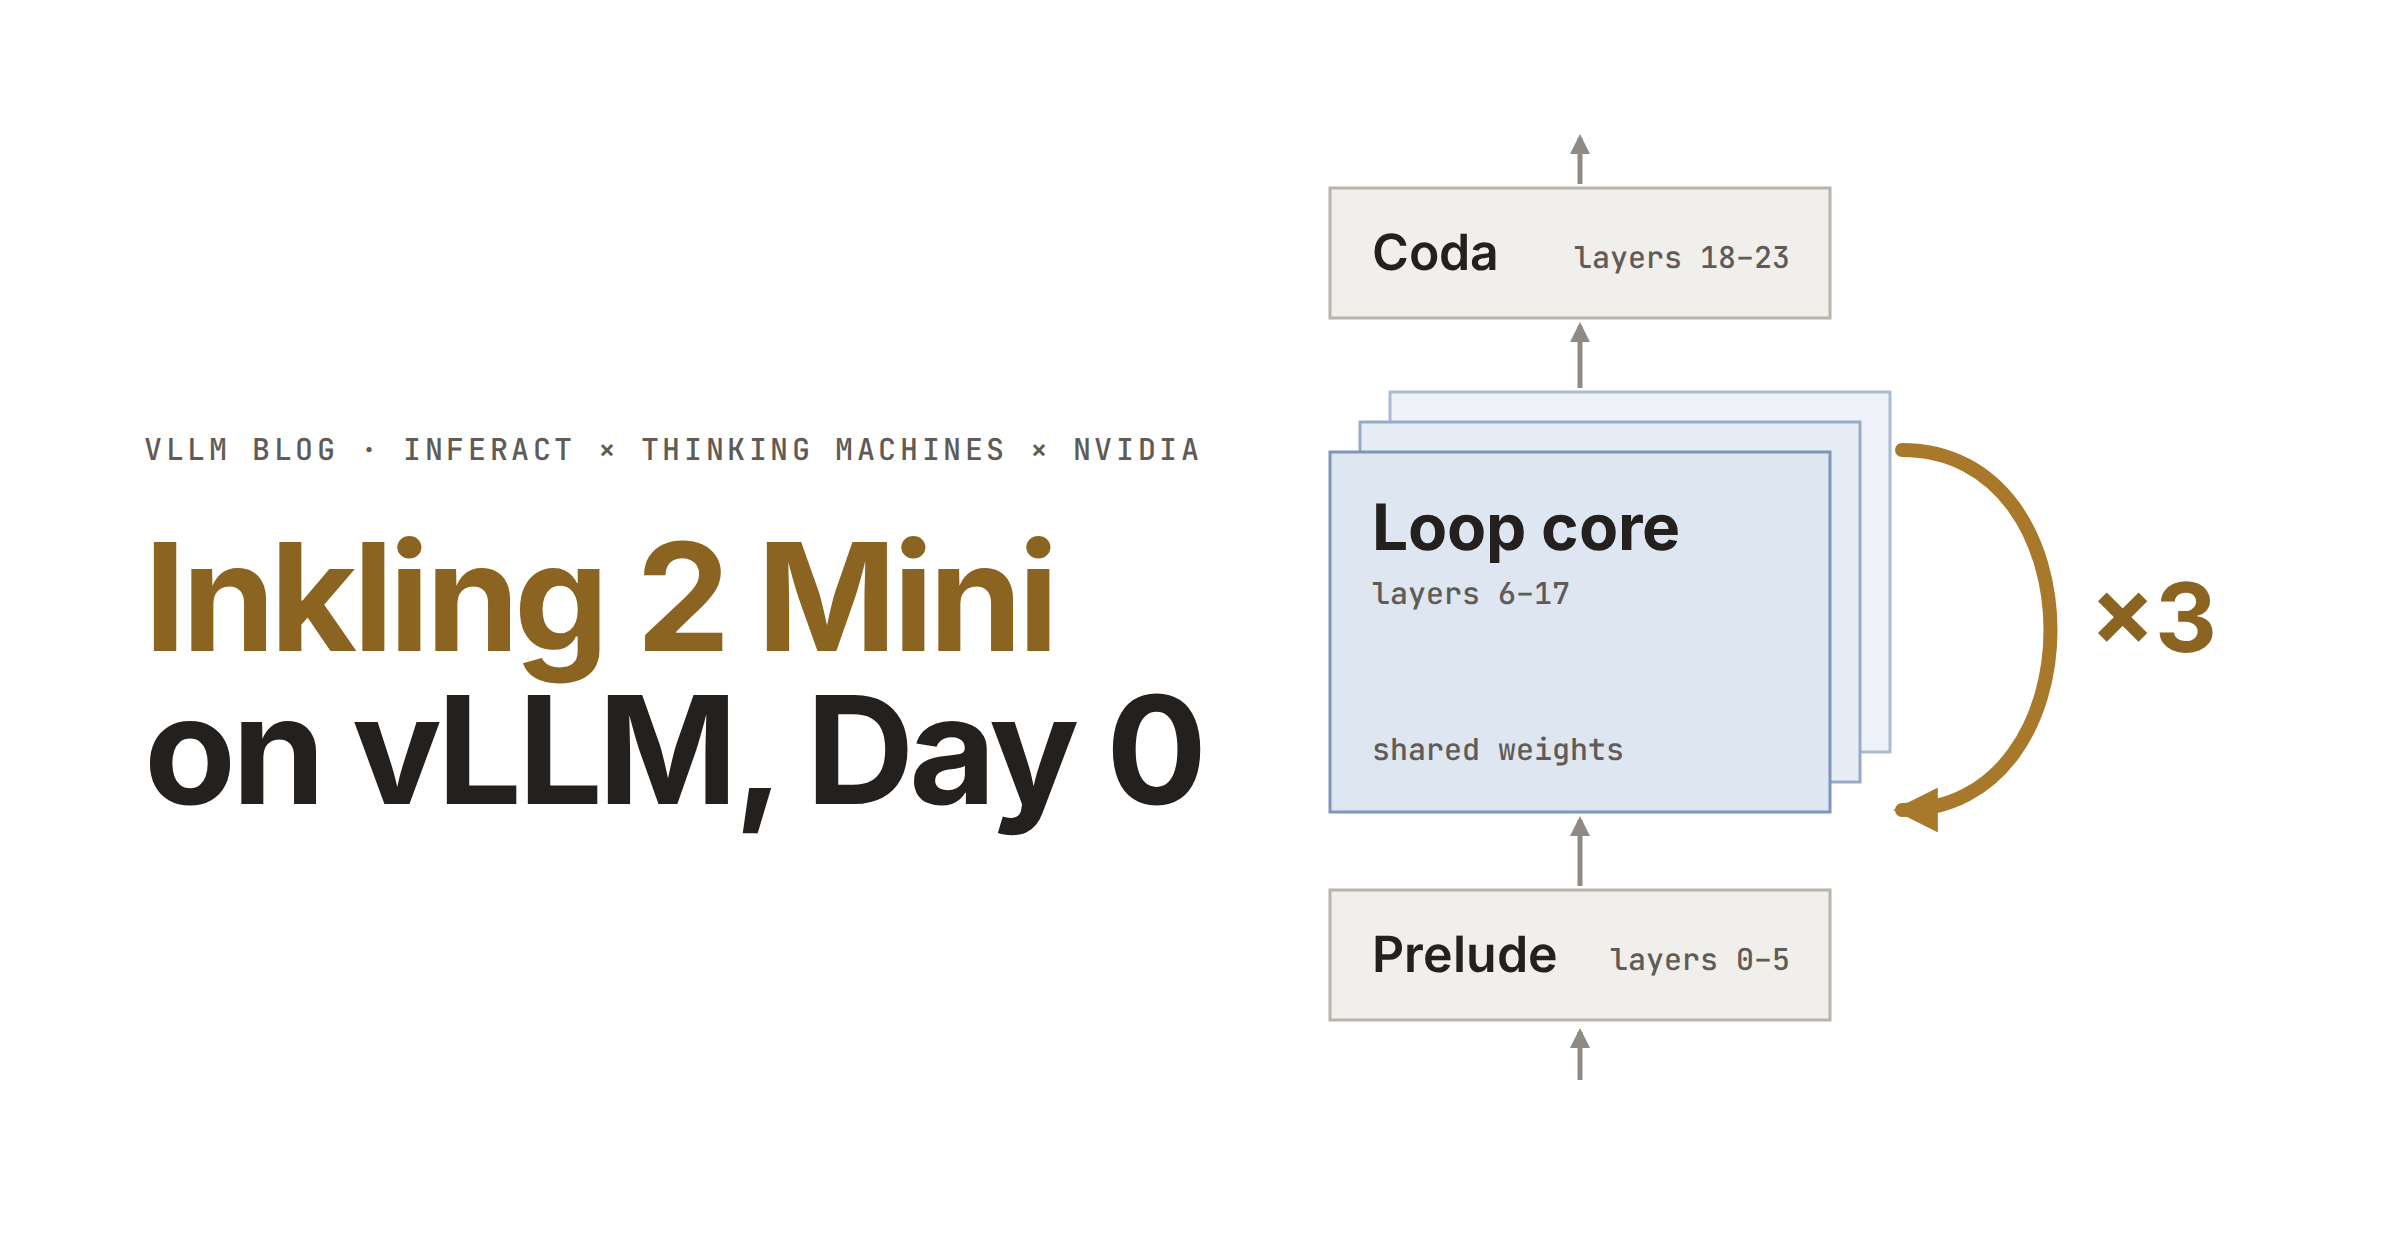
Thinking Machines announced Inkling 2 Mini today. vLLM supports it and its variable-loop research checkpoint, TML-d24-varloop-research, on day 0 on NVIDIA Blackwell, Hopper and DGX Spark. Inkling 2 Mini is a looped model: its middle 12 layers run three times per token with shared weights, each pass with its own KV cache and gated messages from the pass before. It is a multimodal MoE with 26B total and 3.5B active parameters, up to 1M tokens of context and a native DSpark speculator.
TL;DR
- Looped layers. Layers 6–17 run three passes with shared weights. Each pass keeps its own KV cache and reads gated messages from the one before.
- 26B total, 3.5B active, 1M context, Native DSpark. A multimodal MoE built from Inkling 2 Small's components, with NVFP4 experts (MXFP8 in the last 4 layers) and a native DSpark speculator.
- Optimized day-0 support on Blackwell, Hopper and DGX Spark. vLLM manages each pass's caches like any other cache layer, fuses the message reads and controllers, and reuses Inkling 2 Small's fused kernels.
- RL support. vLLM serves Inkling 2 Mini for reinforcement learning with SkyRL.
- Variable-loop research checkpoint. vLLM also serves TML-d24-varloop-research, where you choose the number of passes, and whether the passes share one KV cache, at startup.
#Thinking Machines#Inkling 2 Mini#vLLM#TML-d24-varloop-research#DSpark#Inkling 2 Small#NVIDIA Blackwell#NVIDIA Hopper#NVIDIA DGX Spark