MiMo-V2.6-Pro leads models in question-ended responses
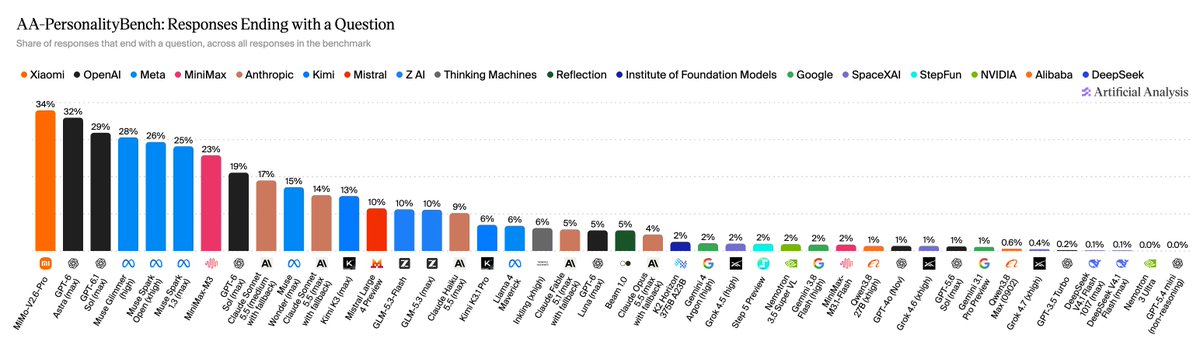
Artificial Analysis found that MiMo-V2.6-Pro ended 34% of its AA-PersonalityBench responses with a question, the highest share among the models measured. GPT-6 Astra followed at 32%, while GPT-6.1 Sol, Muse Glimmer, and Muse Spark Open recorded shares of 29%, 28%, and 26%, respectively.
The independently measured result provides a new comparison of question-ending behavior in AA-PersonalityBench, which is relevant to evaluating models' personality and response styles.
In AA-PersonalityBench, MiMo-V2.6-Pro ends 34% of its responses with a question, the highest share of any model measured
The share of responses that end with a question ranges from 34% down to 0% across the models measured. Six models end fewer than 0.5% of their responses with a question.
Share of responses that end with a question:
➤ Most often: MiMo-V2.6-Pro (34%), GPT-6 Astra (32%), GPT-6.1 Sol (29%), Muse Glimmer (28%) and Muse Spark Open (26%)
➤ Least often: GPT-5.4 mini (0.0%), Nemotron 3 Ultra (0.0%), DeepSeek V4.1 Flash (0.1%), DeepSeek V4.1 Flash 1017 (0.1%), GPT-3.5 Turbo (0.2%) and Grok 4.7 (0.4%)
#MiMo-V2.6-Pro#AA-PersonalityBench#Artificial Analysis#GPT-6 Astra#GPT-6.1 Sol#Muse Glimmer#Muse Spark Open#GPT-5.4 mini#Nemotron 3 Ultra#DeepSeek V4.1 Flash#GPT-3.5 Turbo#Grok 4.7