vLLM Uses Coding Agents to Optimize Kimi K3 Inference on GB300
The vLLM team said it used agent-assisted development to build a unified CuTe DSL decode path for Kimi K3 on NVIDIA GB300 systems, covering attention, MoE and communication across 8 or 16 GPUs. The team reported more than 840 tokens/s at batch size 1 on 16 GPUs with DSpark, 1.5–2× higher decode throughput in several tested configurations and up to 1.8× higher P90 interactivity on AgentX. SemiAnalysis separately reported 423 tok/s/user on GB300 NVL72, a 1.68× speedup, while the figures depend on different configurations and measurement methods.
The optimization shows how coding agents are being used for complex GPU-kernel work, while the associated fast-track review proposal addresses the resulting gap between automated code generation and human validation.
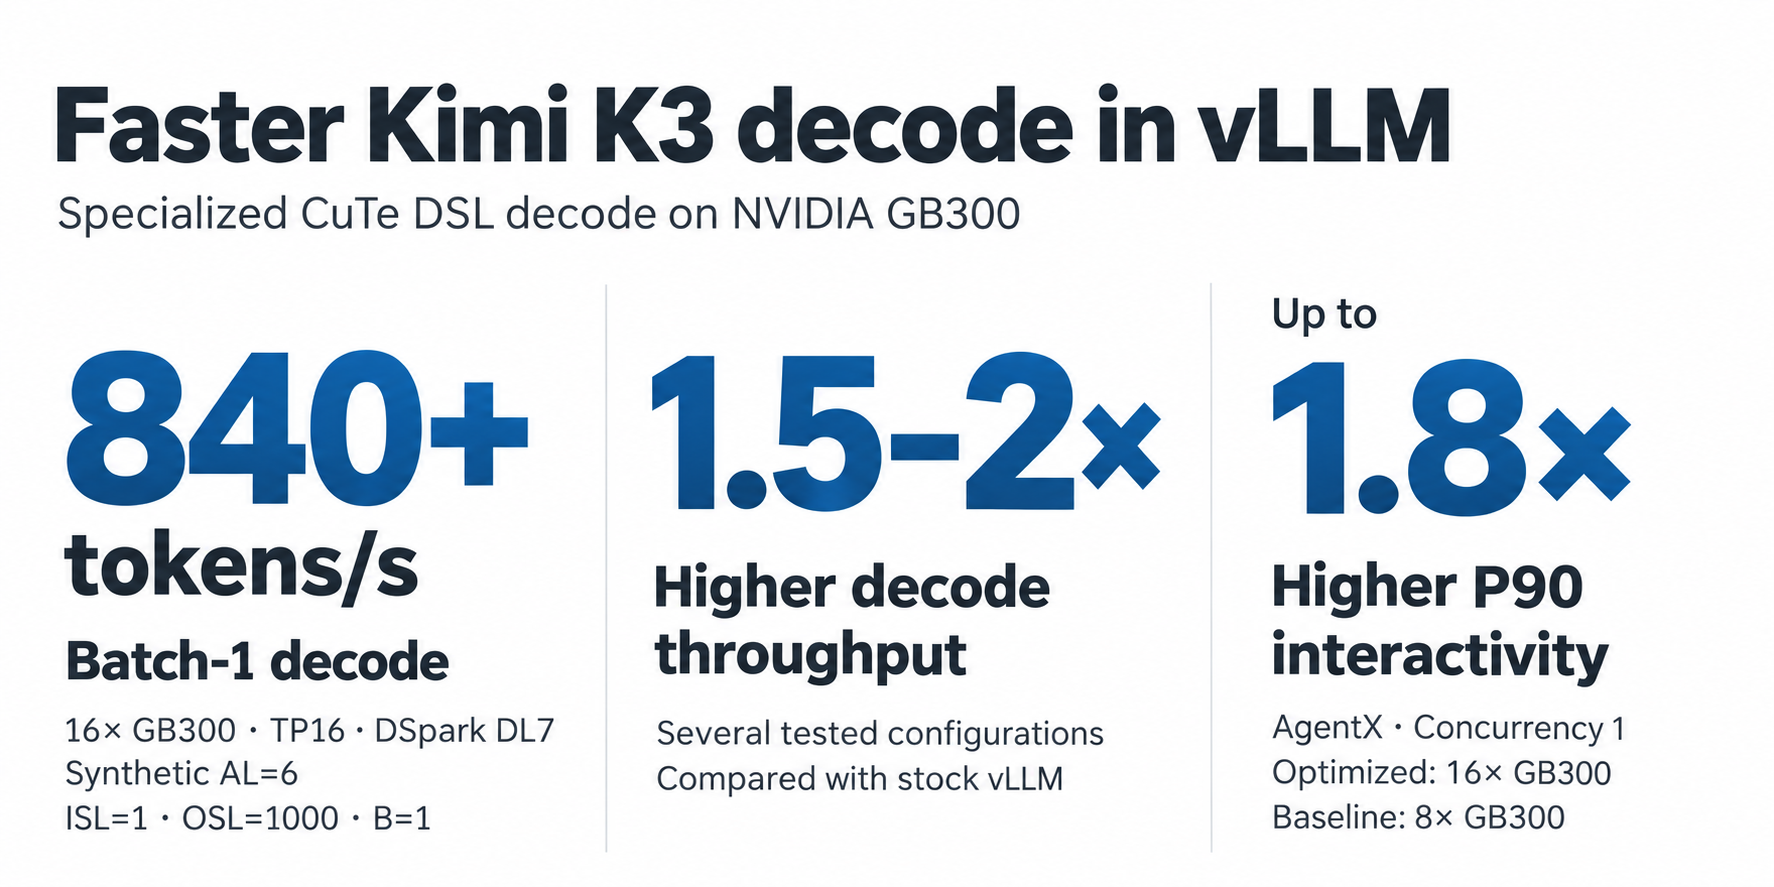
Coding agents can now help with some of the hardest parts of model optimization: writing complex GPU kernels, performing cross-operator fusions, overlapping computation with communication, and tuning execution across different batch sizes and GPU configurations. For Kimi K3, we used agent-assisted development to build a unified CuTe DSL decode path on the NVIDIA GB300, covering attention, MoE, and communication across 8 or 16 GPUs. The optimizations deliver over 840 tokens/s at batch 1 on 16 NVIDIA GB300 GPUs with DSpark (synthetic AL=6), 1.5–2× higher decode throughput in several tested configurations, and up to 1.8× higher P90 interactivity on the AgentX workload.
Agent-optimized inference code is outpacing our review and maintenance workflow. The manual review process of understanding every line of every kernel, mapping out potential issues, and testing every supported configuration, is very time-consuming work. On the other hand, if we omit this work then we risk shipping buggy software that could fail in production.