vLLM开源逐位一致RL训练方案
AI 总结
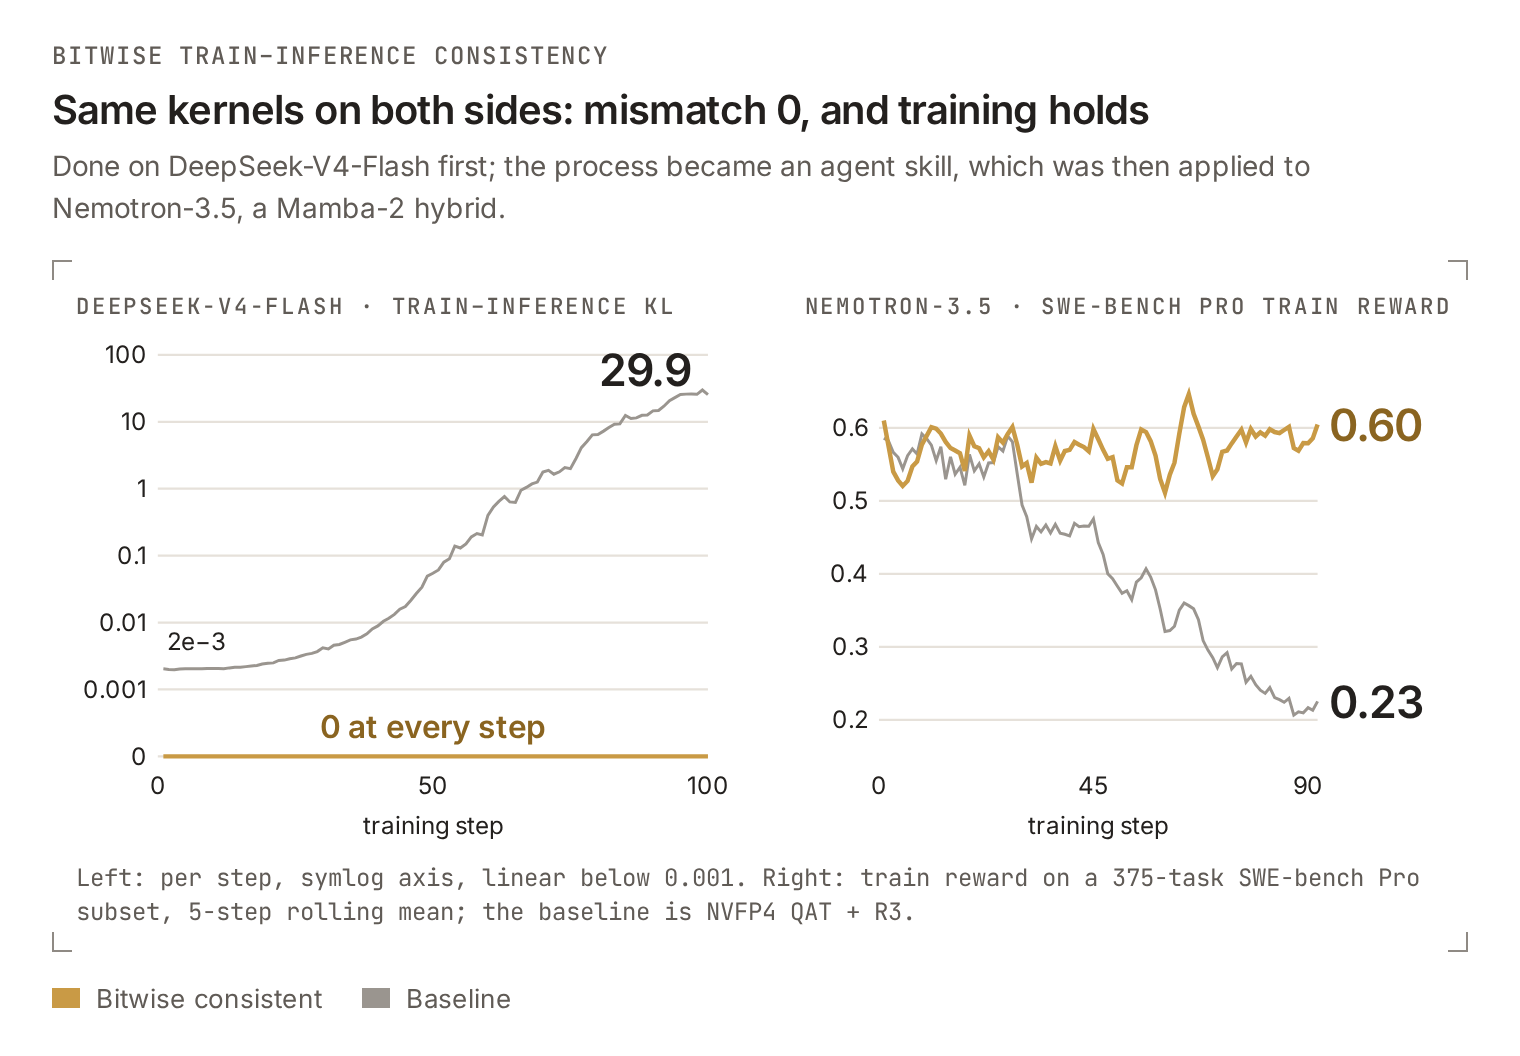
vLLM 团队发布了一套让强化学习训练前向与推理内核逐位一致的方案:训练直接调用 vLLM 推理内核,并修改这些高性能内核,使采样和训练对每个 token 给出完全相同的 logprob。团队称在 DeepSeek-V4-Flash 上,高性能基线的训练-推理 KL 从 2e-3 升至 29.9、奖励回落,而一致版本在 100 步中 diff 始终为 0,rollout 吞吐为基线的 91.3%。在 Nemotron-3.5(Mamba 混合架构、NVFP4)上,一致版本 SWE-bench Pro 分数保持在约 0.6,基线则从 0.56 降至 0.22;相关流程已打包为智能体技能并连同配方与代码开源,DeepSeek-V4.1 的一致性已实现 0 diff,性能优化仍在进行。
深度见解
作者认为,推理侧数值优化会让训练优化的策略偏离实际采样策略,逐位一致可减少崩溃与重跑,从而缩短端到端 RL 训练时间。
TL;DR
- Problem: inference-side optimizations in high-performance RL change the numerics, so training optimizes a policy other than the one that sampled. On DeepSeek-V4-Flash, the high-performance baseline's train-inference KL rose from 2e-3 to 29.9 while reward fell back.
- Approach: the training forward calls vLLM's inference kernels directly, and those high-performance kernels are modified so rollout and training produce bitwise-identical logprobs for every sampled token (diff = 0).
- Results: over 100 DeepSeek-V4-Flash training steps, diff is 0 at every step at 91.3% of the baseline's rollout throughput. Carried over to Nemotron (Mamba hybrid + NVFP4), the consistent run's SWE-bench Pro score holds while the baseline's drops from 0.56 to 0.22.
- Open source: the process is packaged as an agent skill and released with the recipes and code, lowering the cost of doing this on a new model.
- In progress: DeepSeek-V4.1 has reached 0 diff; performance work is being finalized and will get its own post.
#vLLM#DeepSeek-V4-Flash#Nemotron-3.5#DeepSeek-V4.1#NVIDIA#Megatron-LM#verl#DeepGEMM