Finish RL Training Faster: Bitwise-Consistent, High-Performance, Agent-Driven
Source excerpt
We make vLLM rollout and the training forward give bitwise identical logprobs on DeepSeek-V4-Flash and Nemotron-3.5-Lightning-30B-A3B (NVFP4), keep 91% of rollout throughput on DeepSeek-V4-Flash, and open-source the agent skill.
TL;DR
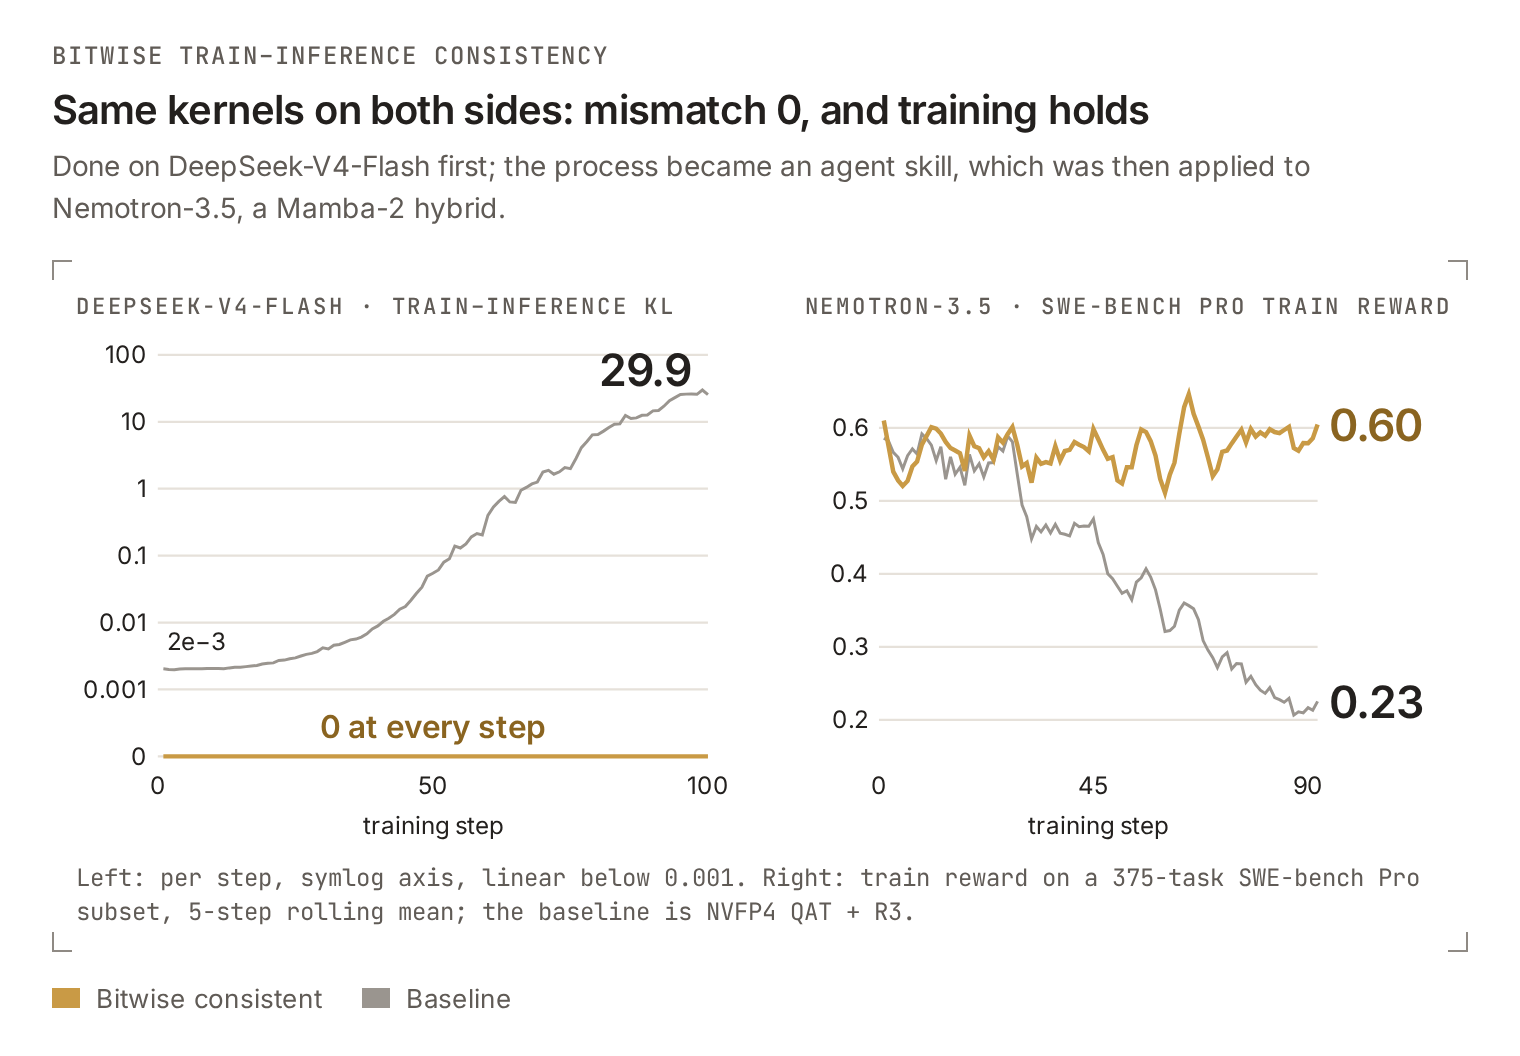
- Problem: inference-side optimizations in high-performance RL change the numerics, so training optimizes a policy other than the one that sampled. On DeepSeek-V4-Flash, the high-performance baseline's train-inference KL rose from 2e-3 to 29.9 while reward fell back.
- Approach: the training forward calls vLLM's inference kernels directly, and those high-performance kernels are modified so rollout and training produce bitwise-identical logprobs for every sampled token (diff = 0).
- Results: over 100 DeepSeek-V4-Flash training steps, diff is 0 at every step at 91.3% of the baseline's rollout throughput. Carried over to Nemotron (Mamba hybrid + NVFP4), the consistent run's SWE-bench Pro score holds while the baseline's drops from 0.56 to 0.22.
- Open source: the process is packaged as an agent skill and released with the recipes and code, lowering the cost of doing this on a new model.
- In progress: DeepSeek-V4.1 has reached 0 diff; performance work is being finalized and will get its own post.
#vLLM#NVIDIA#Inferact#DeepSeek-V4-Flash#Nemotron-3.5#DeepSeek-V4.1#Thinking Machines Lab#slime#SkyRL#PyTorch TorchTitan