vLLM称Vera Rubin吞吐达到GB300的58倍
vLLM称,其服务栈在一台NVIDIA Vera Rubin NVL72机架上达到每GPU每秒170万tokens,同时为每位用户提供每秒387个tokens,较GB300 NVL72提升58倍。项目将结果归因于针对Rubin调整的内核、专用张量并行解码路径、机架级KV缓存与Engram内存池,以及工作负载感知路由。其峰值吞吐为每秒252万tokens,单用户速度达到每秒1,810个tokens。这些数据来自项目方使用SemiAnalysis AgentX基准开展的测试;报告还称,Mooncake KV池向HBM扩展的方案仍处于实验阶段。
该报告具体介绍了机架级推理优化方案,包括针对硬件调整的内核、分布式KV缓存与Engram存储及工作负载感知路由,并说明了相关测量方法。
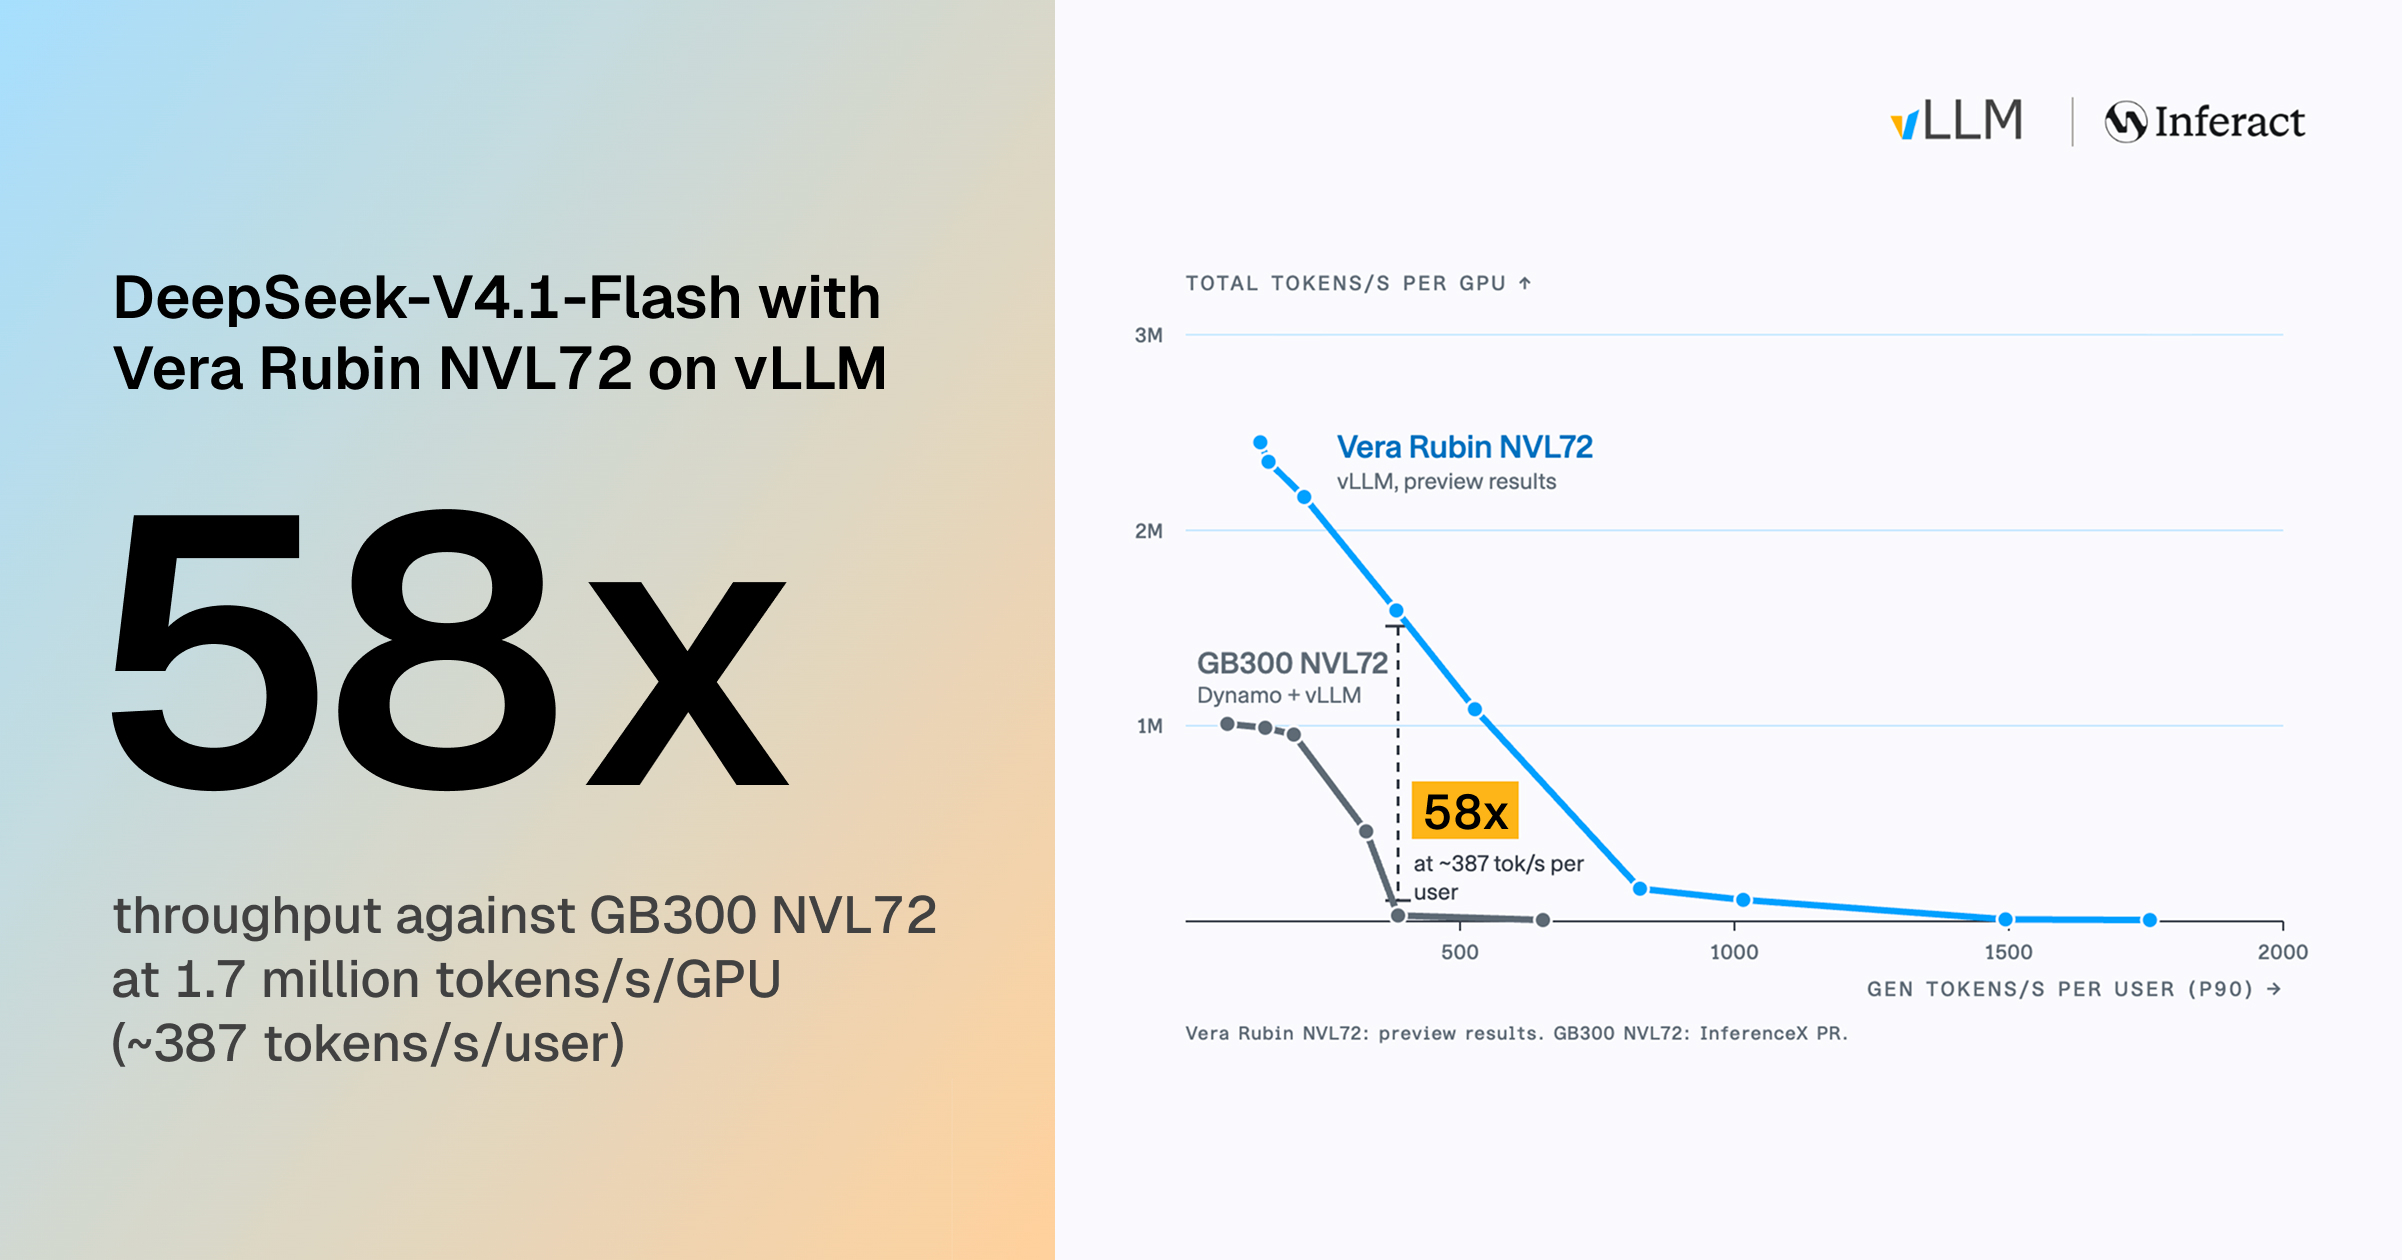
TL;DR: On one NVIDIA Vera Rubin NVL72 rack, vLLM serves DeepSeek-V4.1-Flash at 1.7M tokens/s per GPU while each user gets 387 tokens/s, 58× GB300 NVL72, and reaches 2.52M at peak throughput and 1,810 tokens/s for a single user. The gains come from building on what is new in Rubin: kernels tuned for its split memory and FP4 tensor cores, specialized decode kernels for low latency, and a rack-wide KV cache and Engram tables shared over NVLink.
This is the third post in our DeepSeek-V4.1-Flash series. The first post covered day-0 bring-up and kernel fusions. The second scaled the model to a GB300 NVL72 rack with P/D disaggregation and Wide-EP. This post moves the same stack to Vera Rubin NVL72, which we introduced last month.
Rubin opens up new avenues for optimization. We start with the hardware facts that shaped our work, then go through four groups of optimizations:
#vLLM#DeepSeek-V4.1-Flash#NVIDIA Vera Rubin NVL72#NVIDIA GB300 NVL72#Dynamo#Mooncake#SemiAnalysis AgentX