vLLM Reports 58× Throughput on Vera Rubin for DeepSeek-V4.1-Flash
vLLM says its serving stack achieved 1.7 million tokens per second per GPU on one NVIDIA Vera Rubin NVL72 rack while serving each user at 387 tokens per second, a claimed 58× result versus GB300 NVL72. The project attributed the results to Rubin-tuned kernels, a specialized tensor-parallel decode path, rack-scale KV-cache and Engram memory pools, and workload-aware routing. It also reported peak throughput of 2.52 million tokens per second and 1,810 tokens per second for a single user. The figures came from project-led testing with the SemiAnalysis AgentX benchmark, and the report’s HBM extension of the Mooncake KV pool remained experimental.
The report documents specific rack-scale inference optimizations, including hardware-tuned kernels, distributed KV-cache and Engram storage, and workload-aware routing, together with the methodology used to measure them.
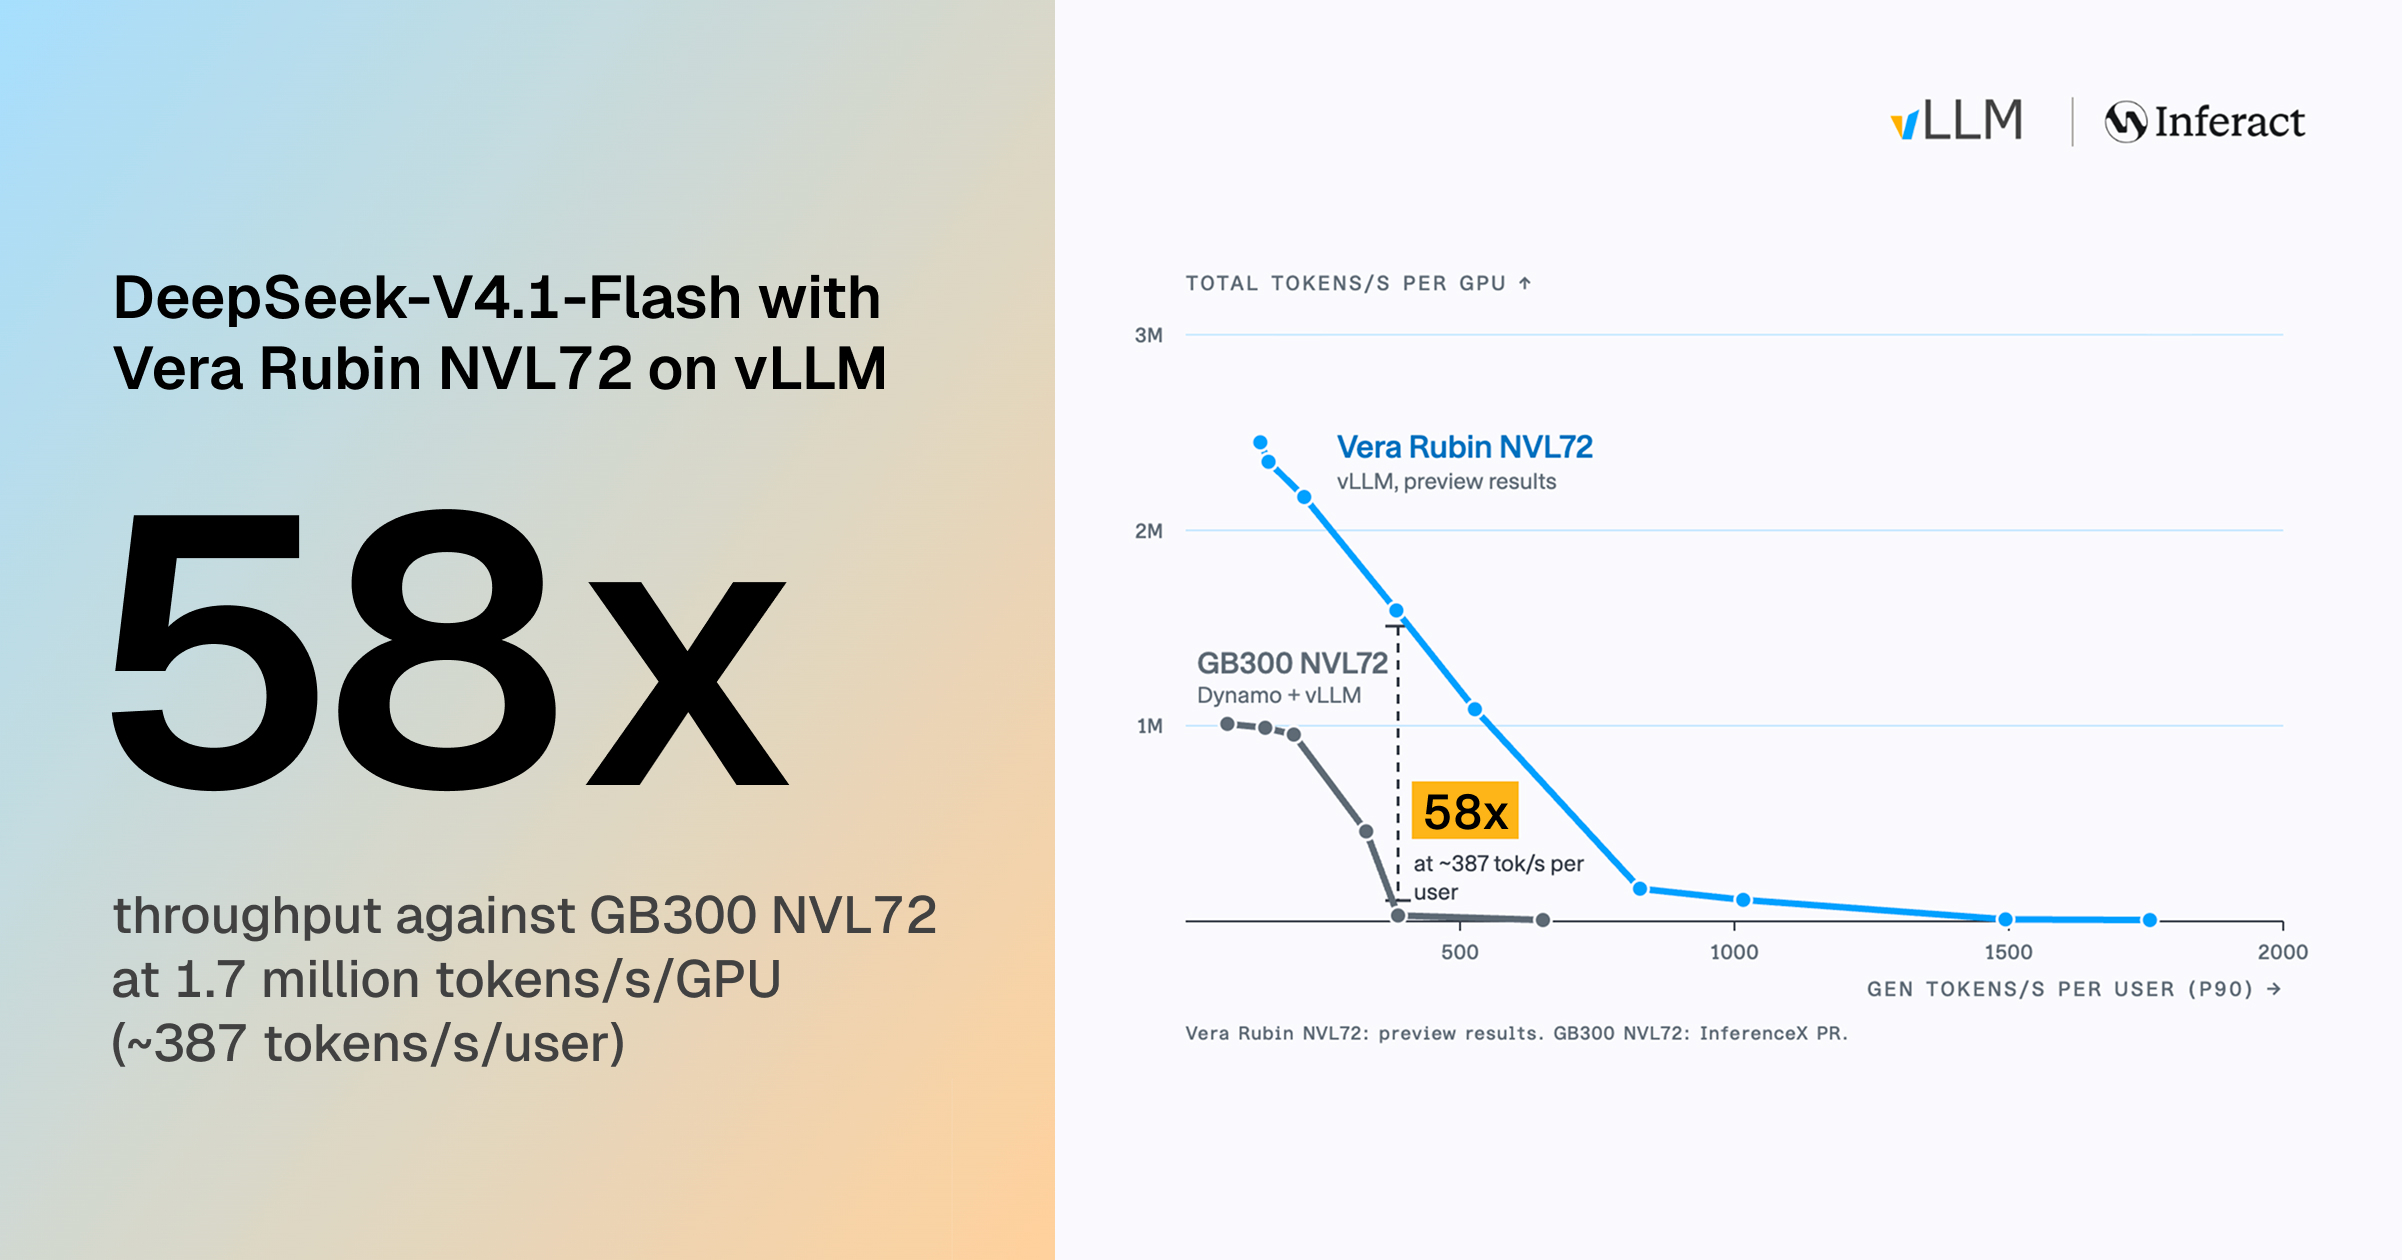
TL;DR: On one NVIDIA Vera Rubin NVL72 rack, vLLM serves DeepSeek-V4.1-Flash at 1.7M tokens/s per GPU while each user gets 387 tokens/s, 58× GB300 NVL72, and reaches 2.52M at peak throughput and 1,810 tokens/s for a single user. The gains come from building on what is new in Rubin: kernels tuned for its split memory and FP4 tensor cores, specialized decode kernels for low latency, and a rack-wide KV cache and Engram tables shared over NVLink.
This is the third post in our DeepSeek-V4.1-Flash series. The first post covered day-0 bring-up and kernel fusions. The second scaled the model to a GB300 NVL72 rack with P/D disaggregation and Wide-EP. This post moves the same stack to Vera Rubin NVL72, which we introduced last month.
Rubin opens up new avenues for optimization. We start with the hardware facts that shaped our work, then go through four groups of optimizations:
#vLLM#DeepSeek-V4.1-Flash#NVIDIA Vera Rubin NVL72#NVIDIA GB300 NVL72#Dynamo#Mooncake#SemiAnalysis AgentX