RadixArk releases DaisyRose-27B agent model
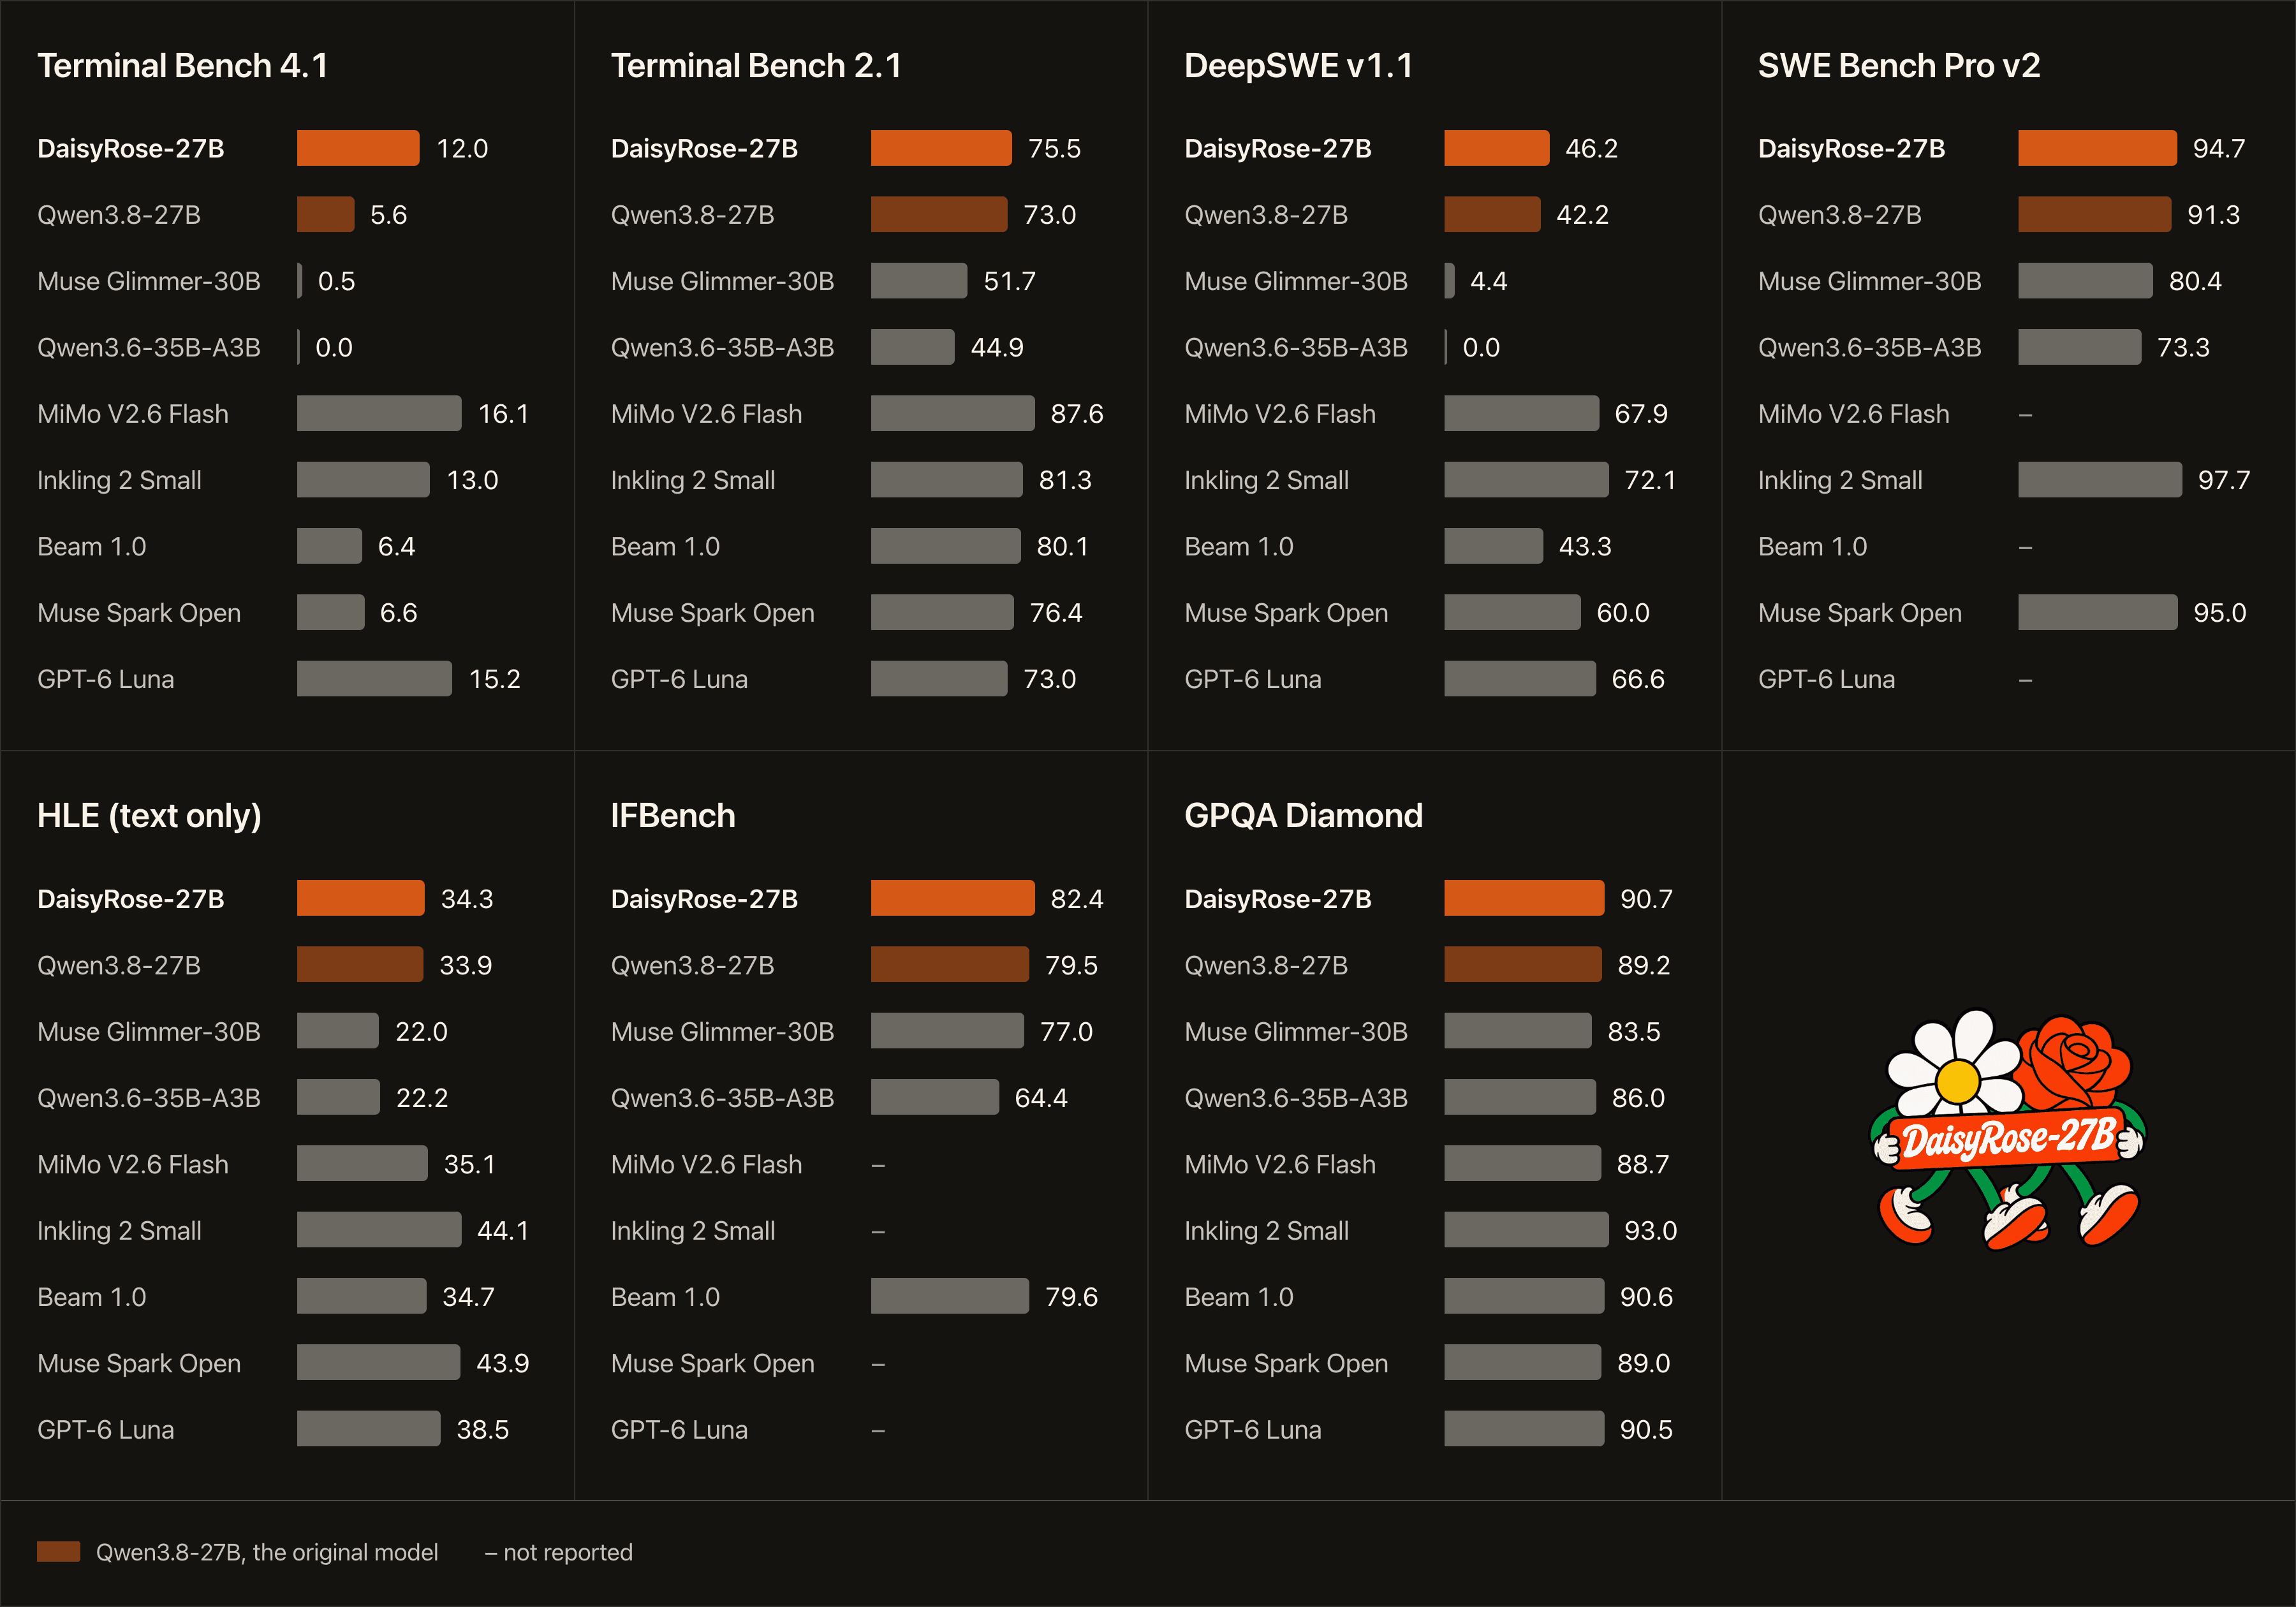
RadixArk released DaisyRose-27B, its first model, built on Qwen3.8-27B and post-trained with reinforcement learning using Miles. The company says it trained the model on 1,200 curated long-horizon agent tasks over 18 days on 144 H200 GPUs, with sessions reaching 1M tokens. RadixArk reported that Terminal-Bench 4.1 pass@1 increased from 5.6% to 12.0%, alongside gains on other reasoning, instruction-following and coding benchmarks; Apache 2.0 BF16, FP8 and NVFP4 checkpoints are available.
The release provides open-weight checkpoints and a detailed account of long-horizon agent post-training, while also offering the open-source Miles reinforcement-learning framework for further experimentation.
Today we are releasing DaisyRose-27B, RadixArk’s first model, built on Qwen3.8-27B and trained with reinforcement learning usingMiles. We trained it on long-horizon agent tasks with sessions up to 1M tokens, with just 1,200 curated tasks in 18 days on 144 H200 GPUs. DaisyRose-27B improves Terminal-Bench 4.1 pass@1 from 5.6% to 12.0%. Beyond Terminal-Bench 4.1, it also delivers gains on a variety of other reasoning, instruction following, and coding benchmarks.
We are releasingBF16,FP8, andNVFP4checkpoints for everyone to try and build on. In this post, we explain how carefully designed tasks and efficient infrastructure made these gains possible on a limited compute budget.
#RadixArk#DaisyRose-27B#Qwen3.8-27B#Miles#Eigent AI#AgentENV#SGLang