Harvard study finds Claude outperformed professional reviews in tested comparison
Reports published by Zimu AI, 36Kr and TMTPost described a Harvard study by Gary King and Steven Worthington comparing 134 pairs of Claude Opus 4.8 and professional human reviews for 124 papers. Claude led across seven review dimensions, while three former journal editors selected its review in 26 of 30 blinded comparisons. A separate claim check reported factual-error rates of 5.5% for Claude and 15.9% for humans. The reports noted limitations: GPT-5.5 served as an AI judge, and the sample primarily involved social-science papers.
The study directly benchmarks AI-generated peer reviews against paid, professional human reviews through blinded comparisons, dimension-level scoring, citation and factual-error checks, and robustness tests. Its main significance is to provide evidence on a specific peer-review workflow, although the AI judging and social-science focus limit broader conclusions.
哈佛拿出了能找到的最强人类审稿团,结果被Claude全线碾压!
同一批124篇论文,两边各写一份审稿意见。七个审稿维度比下来,人类一项都没赢。
3位知名期刊的前编辑被请来盲选,30次里有26次挑了Claude。有一位编辑,10组意见里一次都没选人类。
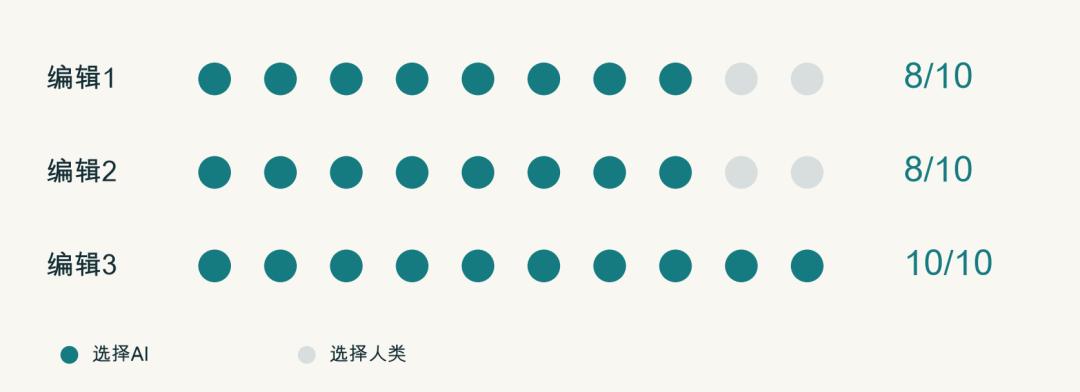
3位前编辑各比10组匿名意见,只看审稿意见,没有重读论文
就连学术圈最怕的「AI胡说」,这回也反转了。
#Harvard University#Gary King#Steven Worthington#Anthropic#Claude Opus 4.8#OpenAI#GPT-5.5#rapidPeer