Firefly describes an AI infrastructure for organizing e-commerce content workflows, converting business workflows into executable Pipeline/DAG plans, and routing tasks among Ray Serve, Ray Data, and elastic compute. The vendor says it uses Lance-based multimodal data tables for asset governance and retrieval, while Trace links tasks, operators, and logs for workflow-level monitoring. These architecture and capability claims come from the Firefly platform team and have not been independently verified.
A Juejin commentary reviews the TRACE system report and the LitTraceQA benchmark for AI scientific question answering. TRACE scored 0.7606 overall on 71 questions, with reported paper-retrieval F1 of 0.9728 and evidence-location F1 of 0.6847, while the report attributes its failures primarily to a “grounding contract gap” in intermediate representations. The review notes limitations including a small sample, incomplete reproducibility, and results that are specific to the benchmark and scorer.
Minjun Kim and Jong Hak Moon submitted TRACE to arXiv on October 19, 2026, introducing a daily-scale framework for predicting in-hospital mortality, prolonged length of stay, and readmission. TRACE organizes EHR data, chest X-rays, radiology reports, and discharge summaries into temporal trajectories while allowing unavailable modalities to contribute no tokens. The paper reports the highest AUROC across all nine dataset-task settings on MIMIC-IV, eICU, and MIMIC-III, with the highest accuracy in eight settings.
Alibaba Qwen and Ohio State University researchers proposed TRACE, a framework that uses rollout-side FP4 quantization outcomes to guide training-side rounding for reinforcement learning of MoE language models. Evaluated on four models across reasoning, coding, and long-horizon RL tasks, the authors report performance comparable to BF16 rollout with joint FP4 weights, activations, and KV cache, plus up to a 5.4× rollout speedup. A compact caching scheme stores selected mantissa and scale information to reduce the overhead of transferring rollout guidance.
What problem it solves
Academic research requires researchers to move through literature work, writing, review, revision, and finalization while preserving the accuracy and integrity of claims. The project addresses this by providing structured skills and an orchestrated pipeline that support research tasks without removing the researcher from important decisions.
Key features
Deep research — Prov…
What problem it solves
Configuring and maintaining a Home Assistant setup through manual interfaces can be time-consuming. AI assistants need structured access to Home Assistant entities, configuration, automations, scripts, dashboards, diagnostics, and administrative operations to support that work.
Key features
Control and inspect Home Assistant — Search for entities, inspect their states, call …
What problem it solves
Learners need a practical path from AI engineering fundamentals to tested systems rather than isolated API examples. The curriculum is structured to make model internals, retrieval pipelines, agent runtimes, evaluation, and failure inspection understandable through runnable code and retained evidence.
Key features
Structured AI engineering curriculum — The curriculum spans m…
What problem it solves
Teams need to understand how AI models describe their products, which competitors appear in answers, and which sources support those observations. Without original answers, citations, execution conditions, and historical runs, it is difficult to investigate visibility findings or determine what to trust.
Key features
Evidence-based visibility research — Enter a domain to see…
What problem it solves
Web automation and end-to-end testing often require coordinating browsers, interactions, assertions, and failure diagnostics. Playwright provides a unified API for driving Chromium, Firefox, and WebKit across tests, scripts, and AI-agent workflows.
Key features
End-to-end test runner — Playwright Test runs end-to-end tests across Chromium, Firefox, and WebKit with browser is…
What problem it solves
Learners need tutoring that can adapt across long-term study, use their own learning materials, and connect answers to sources. They also need a flexible environment for reading, practice, research, visualization, and other agent-assisted workflows without separating each activity from their learning history.
Key features
Personalized agent collaboration — The tutoring envir…
What problem it solves
Coding agents often need to trace API call chains before testing a backend, while regressions can involve changes spread across earlier calls and later reads. shrt records approved call chains and their responses as baselines so later releases can be replayed and compared. When a response changes, it identifies the affected step, field, and potentially responsible write.
Key…
What problem it solves
Developers need to run AI models inside applications while handling model downloads, inference configuration, and chat sessions. The project presents local inference with data privacy and no inference costs as its deployment model.
Key features
High-level application API — The engine exposes a simple API for creating an engine, loading a model, opening a chat session, and re…
What problem it solves
Agent workflows, corrections, debugging patterns, and repository conventions often disappear when a session ends or remain trapped inside one coding tool. Beacon addresses this by capturing session history across harnesses and turning useful findings into reusable memory for future agents.
Key features
Cross-harness session history — Capture session history from Claude Code,…
What problem it solves
Developers need to understand how an application feature works without access to its source code and reproduce that behavior in another project. REA helps investigate application behavior across binaries, application code, and runtime behavior, with results that include evidence and limitations behind each conclusion.
Key features
Agent and terminal workflows — REA connects …
What problem it solves
Teams need to debug, evaluate, monitor, and optimize production AI applications while controlling costs and managing access to models and data. They also need a unified way to track experiments, manage prompts and models, and deploy machine learning systems.
Key features
Observability for LLMs and agents — Capture complete application traces for behavioral insight, and monit…
What problem it solves
Company knowledge is distributed across business systems such as Slack, Google Drive, Jira, GitHub, and Microsoft 365. AI applications need a governed way to search this information, respect each user's access controls, and provide answers that can be traced to their sources.
Key features
Permission-aware enterprise search — Searches connected company systems while applying …
What problem it solves
AI assistants need structured access to design-system data and controls in Figma to extract tokens, inspect components, create designs, and debug design-to-code differences. Teams also need deterministic checks for accessibility, design-code parity, and design-system health without imposing a specific framework or house style.
Key features
Design system extraction and token …
What problem it solves
Running the Kimi K3 model normally presents a storage and memory barrier because its checkpoint is very large. This project provides a portable C99 inference engine that streams model data so the complete model can run on a CPU without requiring GPU infrastructure or a deep-learning framework.
Key features
Portable C99 inference — The engine is implemented in portable C99 an…
What problem it solves
Teams need to capture, search, and analyze multiple observability signals without managing fragmented tools or complex infrastructure. OpenObserve addresses this with a unified platform, a single-binary deployment option, and familiar SQL and PromQL query languages.
Key features
Unified observability — Logs, metrics, traces, RUM, dashboards, alerts, incidents, pipelines, and…
What problem it solves
Teams building retrieval-augmented AI systems need to extract useful knowledge from complex, heterogeneous documents and ground generated answers in traceable evidence. They also need an orchestrated workflow that can combine document understanding, chunking, retrieval, reasoning, and citations.
Key features
Deep document understanding — Extract knowledge from unstructured d…
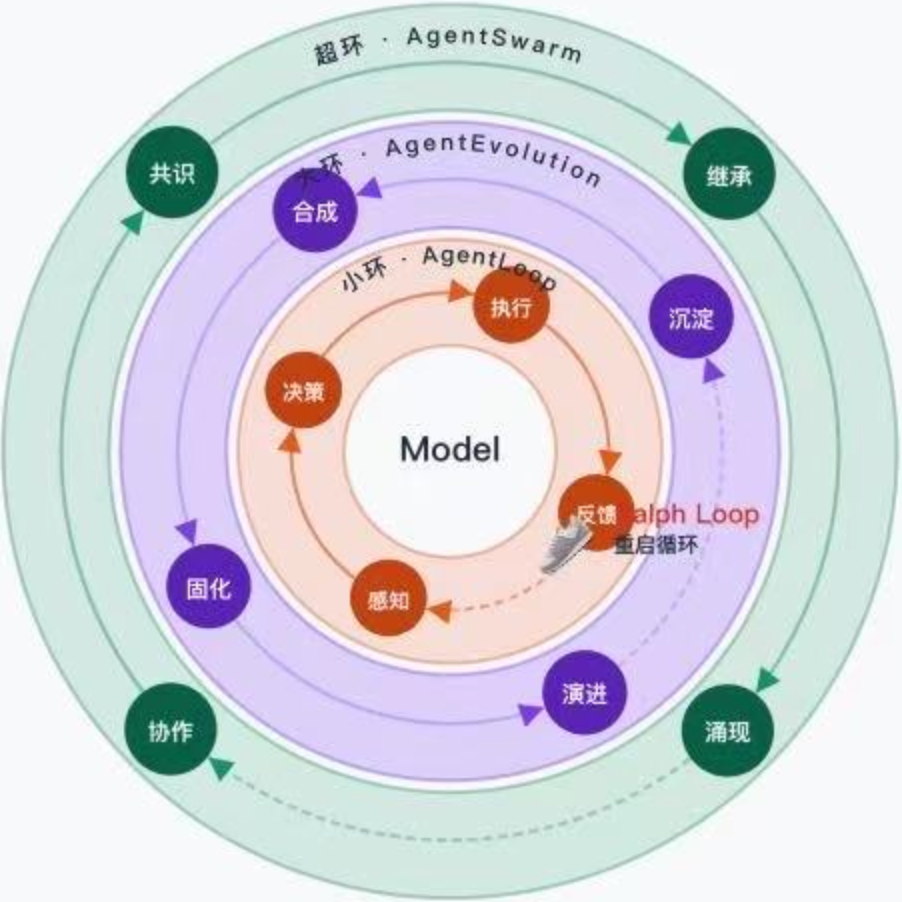
AI has already entered code writing, algorithm optimization, and model development. But after a task is completed, what remains may be reusable capability—or merely an answer and scattered logs. The difference becomes apparent only when a similar problem comes up again: can the system reuse what it learned, or must it pay the cost of exploration all over again?
Recursive Self-Improvement (RSI) co…
BossKey-Stock is a pure terminal-based real-time market monitoring tool for A-shares. No need to open a browser, switch windows, or use an API Key. Press Enter after bosskey, and your terminal becomes a market dashboard full of red and green figures. When you hear someone approaching, press b, and it turns into a perfectly respectable Docker build log.
One-Click Installation
pip install bosskey-s…
 academic-research-skills• Pinned